I design, build, and ship.

Most of my work sits between two questions:

Do I understand the tech deeply enough to see what’s possible?

Have I spent enough time with people to know which problems are worth solving?

Here are a few attempts at answering both.

Building with AI

Yeah

Rotten Tomatoes for YouTube reviews

My role: AI builder + marketer Product → growth

  1. YouTube VideosVideos

  2. Claims ExtractedClaims

  3. Themes SynthesizedThemes

  4. SKUs CataloguedProducts

  5. Verdicts PublishedVerdicts

Can a thousand hours of video become a 30-second decision?

Would I let AI pick my next pair?

More about YeahClose Yeah

AI Builder + Marketer · Still in Love AI Studio · 2026

Runners already share their shoes, training and races on YouTube. I started with shoes, turning that scattered experience into buying decisions linked to their sources. Next, I want to bring that knowledge into a personal agent.

Plate 01 · The verdict card

We put the verdict at the top because, after talking with hundreds of runners from local clubs over the past three years, I know how overwhelming a shoe page can be. Most of us just want to know if it’s worth buying. Everything behind the call is further down, when you want it.

From the product page, yeah.stillinlove.co/p/nike-alphafly-4, 7 Nov 2026.

Plate 02 · The two states

We wait for three creators before we publish a grade, because, as we all know, YouTube is a noisy place. One review could be a one-off opinion. Three distinct creators is an emerging signal, and over time, with more reviews, a consensus forms. Until then, I want to be honest on the page.

The Evidence Gate: 3 distinct creators, and 10 reviews or 30 mentions.

Plate 03 · The spine

The rail on the left is there so you don’t get lost on a long page. It was inspired by Vignelli’s 1972 New York subway map, which showed a journey as one clean line of stops, so you always know where you are and what’s next.

After Massimo Vignelli’s New York City Subway Map, 1972.

Plate 04 · The vote

Every review counts as a vote, and a full review counts for more than a passing mention. Add them up, and the share that says yes makes the call.

The engine’s own trace, as the product shows it under Facts & figures, 7 Nov 2026.
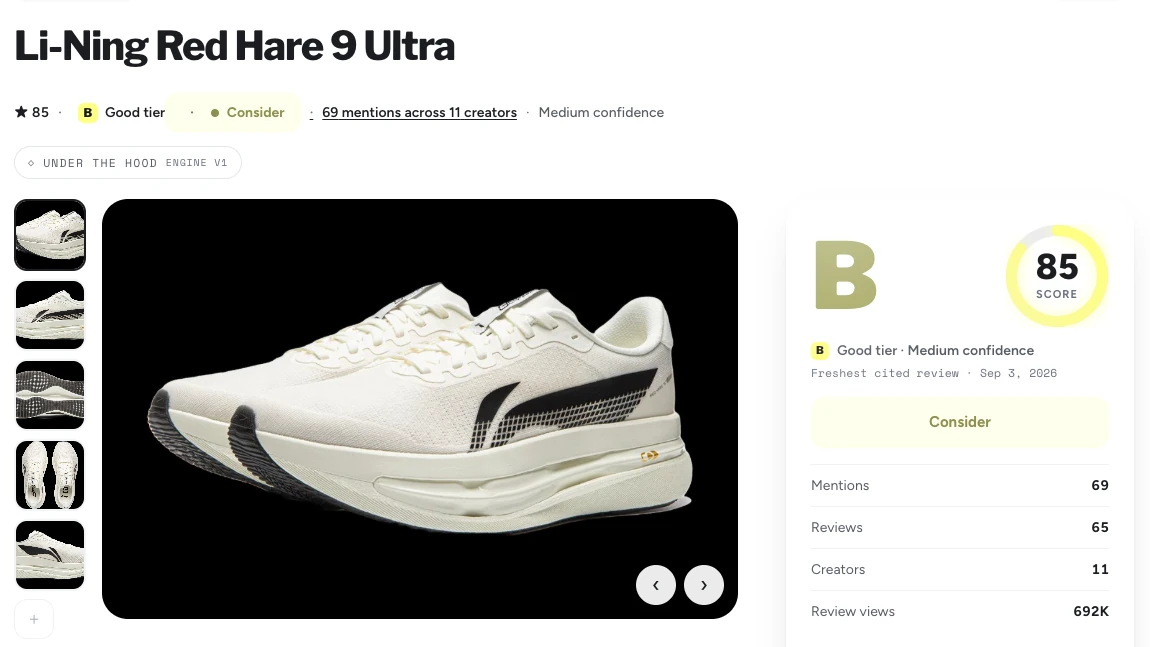
Yeah’s Nike Alphafly 4 product page, with large product imagery, a Consider verdict, confidence, price, and attributed review counts.
Nike Alphafly 4 · Actual product interface · November 2, 2026 · Views are the source reviews’ YouTube viewsView the product ↗
  1. Models synthesize; code owns the sources.

    Code limits what the models can retrieve, tags claims with their sources and checks what the answer says. A runner can explore an unfamiliar recommendation and still trace it back to the evidence.

    1. A paragraph

      Buyer-facing writing points to the themes it draws from.

    2. Its supporting theme

      A theme identifies the particular opinions behind it.

    3. The attributed opinion

      The claim keeps the exact source identity used in synthesis.

    4. The source moment

      The evidence resolves back to the creator's original video and recorded timestamp quality.

    code attaches each link; the model can’t

  2. Change the task, not the model.

    Ruling on absolute truth failed in every trial. I switched to aggregation and kept each failure inside its own item. One bad item no longer had to take down the pipeline.

    July and August 2026 runs · September 2026 record · not live reliability telemetry

    An unsupported claim can be excluded while accepted claims from the same source stay available to later stages.

    A checker that cannot answer is recorded as unverified. Thin output is a recorded yield; infrastructure failures, unusable provider responses and budget refusals can fail the run.

  3. Keep the reviews that disagree.

    A review depends on weight, pace, terrain and foot shape. I put contrasting citations beside supporting ones, so a runner can find the experience closest to their own.

    I set the product direction around a runner’s routine. Category judgment and run-club feedback informed what the system should surface and withhold.

  4. Leave the grade blank when the evidence is thin.

    The Evidence Gate withholds a grade until three distinct creators have reviewed a shoe and there are at least ten reviews or thirty mentions. I’d rather show an incomplete catalog than a full grid of grades the evidence can’t support.

    September 2026 snapshot · 170 of 340 published shoes had fewer than three creators, 164 with the grade withheld · Evidence Gate since June 2026, PR #142

  5. Choose each model by the cost of being wrong.

    I reverted the cheaper extraction model when the number of reviewer opinions extracted per video fell. Coverage became a daily release check alongside category judgment and field testing.

    June 2026 extraction comparison · the reversion is my account

    I steered model choices around cost, risk and capability at each stage. Extraction, discovery and review have different costs of being wrong. A cheaper run is useful only if the evidence remains good enough for the decision.

  6. Show the answer’s limits beside the answer.

    A question about the latest Nike returned mostly non-Nike reviews. Ask Yeah now keeps the requested brand and model in scope, explains what a list is ranked by, and asks for clarification when the request is ambiguous.

    Ask Yeah · September 2026 · implemented and regression-tested

    The earlier word-overlap search always found something. Now Ask Yeah can say “not covered,” offer a clearly labelled alternative, or show no shoes. When the evidence can’t support a full answer, you don’t get one.

    Reviewers keep their names, faces, and source links. Quotation marks identify their exact words; extracted claims are labelled as summaries.

    Tests cover wrong-brand results, missing model generations, ambiguous names, expired answers and source attribution. None of them tell me whether runners make better purchases.

  7. Keep the grade and the explanation apart.

    The grade comes from one engine and the explanation from another. They meet on the runner’s product page.

    The system, end to end.

    Evidence

    Shared source material

    The grade

    Explicit grading rules

    The explanation

    Grounded reasoning

    Publication

    Editorial path only

    Delivery

    Stored grade + current editorial

    Creator reviews

    Independent running-shoe reviews enter through submitted videos, channels, playlists and scheduled discovery. Each voice keeps its identity.

    • The queue distinguishes video, channel, playlist and scheduled acquisition jobs.
    • Source records connect videos to creator metadata.

    Source identity

    Video and channel metadata establish who spoke, what the review covers and where the original can be found.

    • The metadata client uses the official YouTube Data API.
    • Channel, video and playlist lookups preserve their source identifiers.

    Timestamped words

    Transcript segments preserve the reviewer's words and their position in the video, giving later claims a place to point back to.

    • A configurable acquisition chain accepts supplied files and enabled providers.
    • A fetched document must match the requested source ID.

    Evidence store

    Source records and timestamped transcripts are stored before interpretation. Later stages can reuse evidence without acquiring it again.

    • Source artifacts preserve the original transcript payload and acquisition provenance.
    • The ingestion handler reuses existing artifacts before calling a provider.

    Corpus search

    Operators can search the stored transcript corpus without repeatedly parsing every original artifact or making another model call.

    • A rebuildable PostgreSQL full-text projection uses TSVECTOR and a GIN index.
    • This admin-only projection is separate from the original timestamped evidence.

    Mention extraction

    Structured extraction identifies product mentions, resolves which shoe they concern and removes duplicates before they reach the grading engine.

    • Time-marked windows pass through extraction and product resolution.
    • Accepted records are deduplicated and persisted as mentions.

    Stored mentions

    Product-linked review evidence is stored with source identity. This is the input to the deterministic verdict engine.

    • Mention records connect the product, source and extracted review evidence.
    • Recomputation reads those records rather than generated editorial prose.

    Deterministic verdict

    A separate grading engine computes score, tier, verdict and confidence from stored review evidence. The editorial model does not choose the grade.

    • The pure consensus engine applies shared, explicit grading rules.
    • Its result is stored as a product verdict snapshot.

    Attributed opinions

    The editorial pipeline begins by extracting what each reviewer said. An unsupported claim can be removed while faithful claims from the same source survive.

    Input
    Timestamped transcripts
    Output
    Attributed claims
    • Stage A produces source-specific distillates with claim-level admission.
    • The cached output records transcript content, model, prompt and product scope.

    Grounded themes

    Opinions become useful themes: agreement, disagreement, minority views and individual observations. Each theme cites the particular claims that support it.

    Input
    Attributed claims
    Output
    Evidence-backed themes
    • Stage B resolves exact Stage A claim IDs through the harness.
    • A durable product theme set carries the evidence identities used in synthesis.

    Buyer editorial

    Grounded themes become clear writing about who a shoe suits and what tradeoffs reviewers describe. The writing can interpret buyer relevance without inventing product facts.

    Input
    Evidence-backed themes
    Output
    Product graph
    • Stage C rewrites accepted themes and audits for invention or reversal.
    • Its durable draft remains separate from the versioned publication.

    Fidelity checks

    Checks protect against fabrication, distortion and broken traceability. They act on individual claims, themes and paragraphs, while recording what was actually verified.

    • Deterministic validation works alongside configured model verification.
    • Verification coverage and exclusions remain recorded rather than implying universal review.

    Pinned provenance

    A published claim stays connected to the exact evidence used to write it, even if another ingestion run later changes the available corpus.

    • Each selected distillate is pinned by ID with its full cache identity.
    • Theme sets retain those pins for stable publication readback.

    Durable queue

    Work is recorded as database jobs, so acquisition and reasoning can continue independently of a page request or an operator's session.

    • Active jobs are deduplicated by kind and entity.
    • Workers claim queued rows with FOR UPDATE SKIP LOCKED.

    Bounded workers

    Workers claim a job, process its units and record progress. A maintenance pass recovers stale work and keeps operational state visible.

    • The worker dispatches registered handlers outside the short claim transaction.
    • Heartbeats and a stale-job sweep support recovery.

    Progress checkpoints

    Completed units are recorded as work proceeds. A recovered job can continue from its progress instead of repeating every finished unit.

    • The worker commits per-unit progress and refreshes heartbeats.
    • Budget pauses preserve the job's recorded progress.

    Bounded recovery

    Recovery handles infrastructure and unusable provider responses without repeatedly regenerating sound evidence because a checker disliked the content.

    • The reasoning harness bounds producer retries and distinguishes infrastructure failures from low yield.
    • Stages reuse durable upstream outputs rather than discarding valid prior work.

    Spend controls

    An estimate precedes execution. Per-call usage is recorded and reconciled, while a daily spend check can stop workers from claiming more billable work.

    • The ledger stores estimated and actual cost, and jobs can pause for budget.
    • In-flight work can still overshoot; this is not an exactly-once spending guarantee.

    Models by role

    Extraction, synthesis, writing and verification have distinct model roles. A run records its chosen configuration instead of leaving the model identity implicit.

    • Explicit request choices override saved prompt choices and curated defaults.
    • The runtime supports configured transports and records routing violations.

    Durable stage outputs

    Opinions, themes and draft editorial have their own stored outputs. One stage's failure does not require purchasing the work of every earlier stage again.

    • Distillates, product theme sets and editorial drafts are persisted independently.
    • Model, prompt and contract identity distinguish reusable outputs.

    Publication preview

    The operator can inspect the exact buyer-facing package before publishing a version. Its prose, citations and lineage are captured together.

    • The publication bridge exposes a free preview and idempotent version creation.
    • Its frozen public record excludes private runtime and transcript payloads.

    Explicit activation

    A published candidate becomes the current editorial only through an explicit activation choice. Producing a draft and making it public are distinct actions.

    • The bridge appends a version linked to its source run.
    • Only an explicit make_current choice changes the active editorial.

    Version rollback

    A previous editorial version can be restored without asking a model to recreate what the reader saw before.

    • The publication bridge retains version and previous-version identity.
    • Its rollback operation restores the previously current editorial.

    Stored-result API

    The product endpoint reads stored verdicts, editorial and evidence. Opening a product page does not launch the reasoning pipeline.

    • The product response combines separately stored outputs.
    • Import-boundary tests keep model runtime and pipeline modules out of the public read path.

    A useful answer

    The buyer sees a verdict, an explanation and the sources behind it. Separate systems come together in one understandable product page.

    • The frontend displays the backend's verdict rather than recomputing a grade.
    • Evidence links expose source identity and timestamp quality.

    Discovery surfaces

    Published product and source context also supports discovery through feeds, creator pages and rankings. Evidence becomes part of finding the product, not only explaining it.

    • The feed reuses the shared publication predicate.
    • Frontend clients expose creator and contribution leaderboard surfaces.

    Typed contracts

    Explicit data contracts connect Python services and the TypeScript interface. Optional additions preserve older responses while the system evolves.

    • Strict Pydantic models define consensus inputs and outputs.
    • The frontend's additive reasoning contract preserves the existing editorial surface.

    Pinned dependencies

    The backend CI installs a frozen dependency set so validation runs against the versions recorded in the repository.

    • CI installs Python through uv and uses uv sync --frozen.
    • The checked-in lockfile controls dependency resolution.

    Hermetic validation

    Backend CI tests behavior without provider calls or production data. Focused contracts protect the separation between reasoning, evidence and public reading.

    • GitHub Actions runs pytest and a blocking lint check over the transcript surface.
    • Publication tests check that evidence readback uses pinned source records.

    Review artifacts

    A branch and pull request carry each implementation slice into review. Recorded changes and check output give the next reviewer a durable starting point.

    • The operating model names GitHub PRs as the shared review artifact.
    • It requires command output rather than an unsupported claim that checks passed.

    Runtime

    Safeguards

    Toolchain

    Spend checks can stop new billable work; in-flight work can still overshoot. This map shows how it’s built, not live operational telemetry.

Atomic + JournalKit

iOS voice journal that compounds intent

My role: AI builder iOS development

1% better, each day

  • Reflection
  • Key points
  • Questions to sit with

Can the system absorb every new model while the interface gets simpler?

Am I a little wiser than yesterday?

More about Atomic + JournalKitClose Atomic + JournalKit

AI Builder · Still in Love AI Studio · 2026

Every new model, skill and reasoning method adds another choice. I wanted the product to absorb that complexity, so people could start with what was on their minds. I pictured something like Dumbledore’s Pensieve: a place to revisit a thought, recover a memory and see connections we might otherwise miss.

Capture
Journal
Result

Native app screens · Demo entries

  1. Keep the source distinct.

    Speech becomes a transcript on the device. Each edit saves a new revision of the same entry, and every run is tied to the exact revision it used.

  2. Record every run and check its result.

    JournalKit records each run and its spend, to prevent silently repeated work. Each result must fit its route’s format, and Research may cite only sources it retrieved.

  3. Leave room for an unresolved thought.

    Debate lets positions inform one another, then returns a synthesis alongside what remains uncertain. Expand keeps possibilities, risks and open questions in view.

  4. Let the person choose the direction.

    The person picks Journal, Expand, Debate or Research; the server then picks the model configured for that route.

  1. Atomic · on device

    Capture the thought

    SpeechAnalyzer turns speech into a transcript.

  2. Atomic → JournalKit

    Choose a direction

    I left the direction to the person: Journal, Expand, Debate or Research. Each run is tied to the exact saved revision, and the server confirms it’s available.

  3. JournalKit · server

    Run bounded reasoning
  4. Back to the author

    Keep a source-linked result

JournalKit’s Studio also lets authors choose Library context and has a separate skills workbench. Atomic’s Expand route makes a bounded structured call and does not run Studio’s skill chain.

Four ways to develop the same thought

Journal
Reflection · Key points · Questions to sit with
Expand
Core idea · Possibilities and risks · Next steps and questions
Debate
Positions in dialogue · Synthesis · Recommendation and uncertainty
Research
Cited findings · Recommendations · Open questions

Illustrative only: it uses no recording, private thought or live model call.

Agentic Development

Autonomy, guided by judgment

My role: AI builder Code → evals

How do you build a dependable system out of probabilistic agents?

Do I understand what I ship well enough to stand behind it?

More about Agentic DevelopmentClose Agentic Development

AI Builder · Still in Love AI Studio · 2026

Autonomy amplifies outdated specs, weak tests and shared-state mistakes. I ran into all three and changed my controls.

The cases span nine repositories. Authorization and enforcement varied by project.

9 repositories · 1,504 merged PRs · 6 months

Operating cases: March 12–September 8, 2026. Charts: all of 2026, through November 3.

  1. Limit what each session may do.

    On Yeah’s growth work, I let each session open one review-ready pull request. Merging, writing to production and spending money stayed off-limits, even once the task was done.

    The August 27 brief defined the permitted work and stopping conditions. Handoffs recorded the starting state and next assignment, so another session could continue within the same limits.

    The record shows what was permitted; it does not independently verify what ran overnight.

  2. Put the product rules above the tests.

    Agents reverted a correct Yeah fix at least four times because tests defended outdated behavior. I made the product rules authoritative and rewrote the tests around what may be rejected.

    Voice note
    Decision record
    1. Question
    2. Objective
    3. Non-goals
    4. Hard stops

    Rejection was limited to fabrication, material distortion, or broken traceability. Disagreement and low counts were not exclusion criteria. Any new rejection rule required an explicit product decision.

    Parsing and provider failures still required separate fixes. Changing the rules alone did not restore the pipeline.

  3. Bound scope before granting autonomy.

    Seven approval gates delayed a JournalKit campaign. Broader autonomy then turned my oversized brief into overbuilding. I set a 3,000-line ceiling, zero new tables, a provider-spend cap and a reachability check.

    Shared brief

    Context + hard stops

    APIOwner A · own worktree
    WebOwner B · own worktree

    The implementation still reached 3,705 lines. The agent also stopped at an acceptance condition I had written incorrectly; I corrected it and recorded the decision. The campaign closed partly complete.

    These were self-checked constraints.

  4. Isolate coordination state.

    Four sessions sharing one coordination checkout committed each other’s files. Code worktrees were isolated; coordination files were still shared. I added per-session coordination worktrees and commits that name exact file paths.

    ControlReview releasedDeploy waiting
    ImplementRequest sent
    ReviewReleased
    VerifyResult returned

    The growth program ran four peer sessions plus CONTROL, with write manifests, request files and numbered rulings on a branch that never deployed. Documents and people relayed decisions between sessions.

    File isolation did not prevent later conflicts between contract definitions. CI enforcement of write manifests remained proposed.

  5. Make review findings falsifiable.

    Re-measuring downgraded two High-severity findings in this portfolio’s audit, to Medium and Low. Both fixes stayed. Pinning one revision meant only the assessment changed.

    Pinned revision
    Heading scaleHigh → Medium
    Particle motionHigh → Low
    Re-measure
    BuildCheckEvidence

    Severity revised. Fixes retained.

    Review prompts distinguish measured facts from beliefs and require attempts to refute each finding. A written response and a 41-check verifier made the disagreement inspectable.

    This case does not establish a reviewer-accuracy rate or a review policy shared by every repository.
  6. Test whether the test can fail.

    Deleting the résumé privacy guard left all 134 tests passing: the test’s sample data failed an earlier structure check before it reached the guard. I changed the sample; removing the guard then failed the test.

    Evaluation loop · demonstration
    1. CI passes
    2. Counterexample
    3. Revise
    4. Test updated
    Merge held for judgment

    The new sample put contact-like text in an otherwise valid claim field, so it passed earlier validation and reached the privacy rule.

    This was a targeted mutation check on the public résumé contract, not a production removal or a claim of complete mutation coverage.

  7. Validate even an approved plan.

    I endorsed a recovery runbook that would have disrupted registered worktrees. The executing agent found a checkout the plan had missed and stopped before the destructive step. We retracted the runbook.

    Scoped instructionInspect · prepare · verify
    ServerResult returned

    The runbook’s own checks had passed. Separately, destructive Atomic migrations required an authorization naming the migration and its exact revision, so each permission covered only that action.

    At the audit cutoff, only one of the nine repositories had a server-side required CI check.

  8. Turn missed interactions into requirements.

    A retrospective found that an older code path had retired at least 48 operator-activated editorials. Earlier reviews and tests had missed the interaction. I filed CONTROL-003 in the development queue; the correction was still open at the audit cutoff.

    Recorded failureTwo writers interfered.
    Next briefVerify both writers against the same state.
    Correction pending

    The September 8 retrospective used the August 26 database snapshot. It showed two code paths writing to the same records, an interaction no earlier test or worklog had recorded.

    The record shows a correction request, not a shipped repair or an enforced prevention rule.

All 2026 work

What the agents built.

Jan 1 to Nov 3: 14 projects, and 1,774 merged pull requests across 20 repositories.

A commit is one saved change to code; a pull request bundles commits for review before they merge. Area is commits, my own work only (126 commits by others are left out). Projects under 1% share one tile. I committed on 216 of the 242 days since March 7.

Yeah Jun 5 to Nov 3

AI shopping research, starting with running shoes.

  • yeah: 761 commits, 239 PRs
  • yeah-web: 823 commits, 401 PRs

Models synthesize; code owns the sources. A deterministic Python harness assigns claim IDs and owns provenance while the model does the synthesis.

Foundry Oct 11 to Nov 3

Ad concepts from a company's own site.

This portfolio May 27 to Nov 3

This site plus its blog reader.

Derive the numbers from the records. “These values derive from the same normalized records as the chart.”

Atomic Mar 7 to Nov 2

A voice-first iOS app.

Keep the source distinct. Each edit saves a new revision of the same entry, and every run is tied to the exact revision it used.

bubble Apr 1 to May 3

An early web prototype.

journalkit May 27 to Oct 1

A blog engine and a review app.

  • journalkit: 357 commits, 279 PRs
  • lens: 3 commits, 1 PRs

Make a changed assumption fail visibly. JournalKit pins OpenAPI contracts by SHA-256 hash.
Halftime Apr 28 to Sep 1

A pilot product, details withheld.

rule72 Jun 24 to Jul 13

Creator sentiment from finance YouTube.

  • rule72: 138 commits, 52 PRs
  • rule72-web: 93 commits, 73 PRs

Jolly Oct 4 to Oct 28

A plush-toy waitlist and design site.

5 small projects Mar 30 to Oct 30

  • stillinlove The Still in Love studio splash page
  • Saltwater Squish A storefront prototype
  • ai-research A text-first research knowledge base of sourced AI notes
  • Quantum Garage An interactive résumé prototype
  • experiments Visual design experiments

Hairlines: weekly commits, Mar to Nov; each tile to its own peak. Smallest here: and .

Week by week: peak Jun 22, 400 commits

77B tokens processed on my laptop since Apr 1, 96% of them re-reads of cached context.

The build, week by week
Commits
Merged PRs
Active repositories
Coding-agent tokenslaptop, from Apr 1
Tools, servers and skillsin use; laptop, from Apr 1

A commit is one saved change to code; a merged PR, a reviewed batch of them. Tokens are chunks of text the agents read and write (grey, my laptop, from Apr 1). One column per week from Mar 2; each row scales to its own busiest week. Totals at right.

The full ledger: every model, tool and data table

Usage records

Machine AOrchestrator and Coordinator Agents365.4M tokens per recorded day · 211 recorded daysApr 1–Nov 3, 2026

Machine BAlways-On Worker Agents on DigitalOcean VPS≈220.5M tokens per active day · 117 active daysReported Sep 3, 2026

tokens per recorded dayPeak · Sep 27, 2026 · 2.49B tokens · $1,625.85 reported cost · 97% cache-read

Use Left and Right Arrow to explore recorded days. Home and End jump to the first and last records. Escape returns to the peak.

Recording windows differ. B’s dashed line is an active-day average, not a daily record. Tokens include input, output and cache; costs are tool-reported, not invoices.

≈585.9M tokens per day.≈102.9B tokens recorded across both machines.$70,091 in cumulative reported cost.

The daily series is Machine A; B is an earlier aggregate. The headline daily figure adds averages across different recording windows. Tokens include cache; costs are tool-reported, not invoices. VPS totals do not establish continuous coding-agent execution.

0 → 1 Product

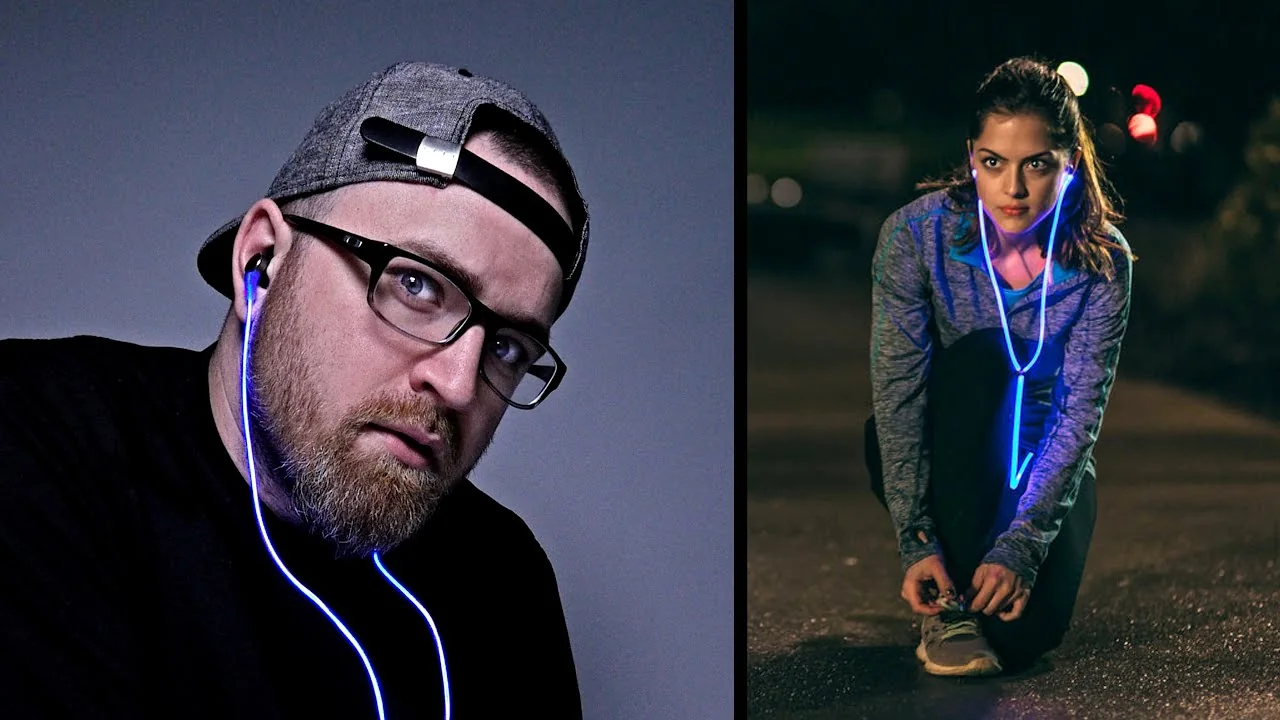
Glow

World’s First Laser Headphones

My role: Inventor + founder Development → production

Can light-diffusing fiber make passive headphones responsive?

Would anyone want to wear these?

More about GlowClose Glow

Inventor, Founder + CEO · Quantum Bakery · 2016–2018

Glow brought Corning’s light-diffusing fiber into a pair of headphones.

  1. Take the design through the factory.

    I led industrial design, engineering, and factory validation in Dongguan, then carried the design into manufacturing.

    30K
    units
    $1M
    sales

    Before acquisition

  2. Build the community alongside it.

    We developed the product and its community together.

    $530K
    Kickstarter · first seven days
    550K
    community

ACME Lab

Ambient computing. The space is the interface.

My role: Head of product Research → pilots

2 LiDARs · 4 laser projectors
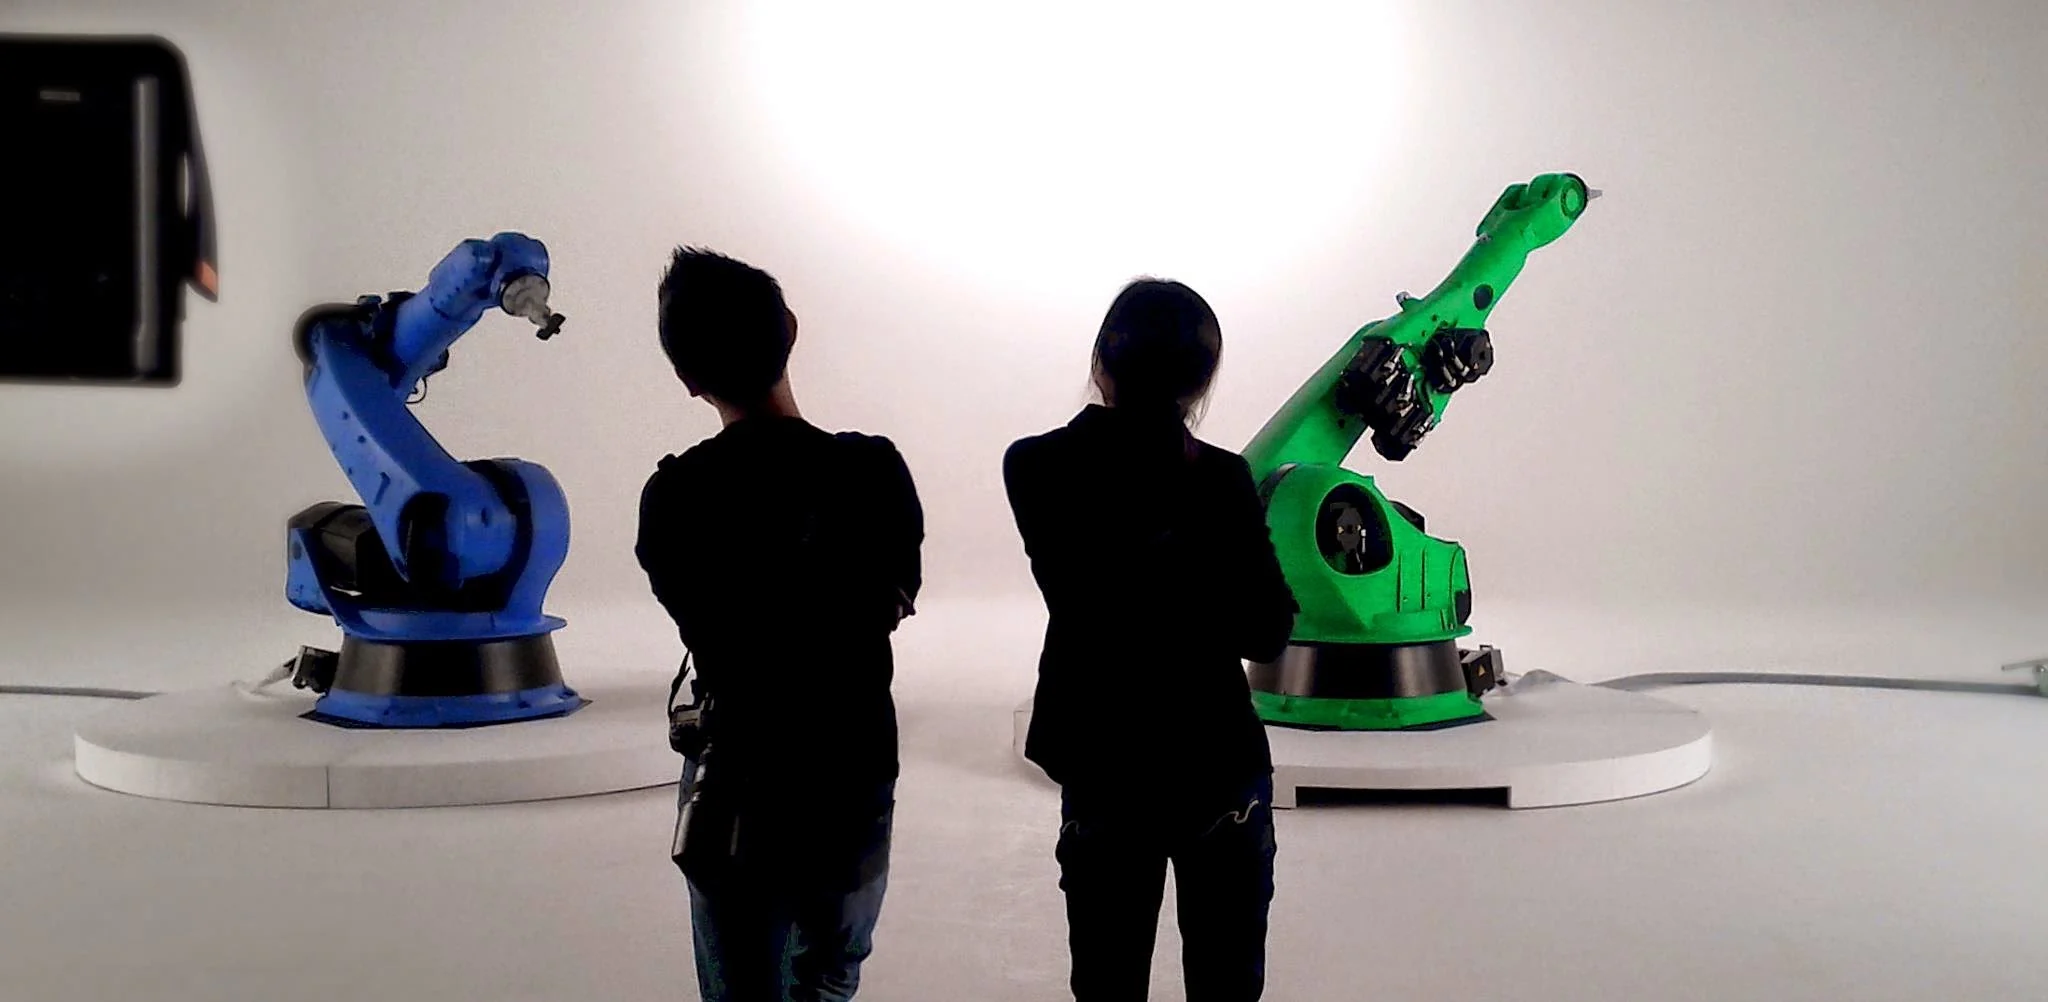
Dot-matrix wall · 2 KUKA arms

Sensing, display and assembly.

In a hangar-sized lab on Villa Street, we brought sensing, room-scale displays and robotic assembly into one physical environment.

Location and context.

Two LiDARs were deployed. The question was how location, context and human intent could inform the space around a person.

Architectural-scale displays.

A giant dot-matrix wall and four laser projectors made the environment a display. The projection screen was roughly the size of a basketball court.

Robotic assembly.

Two large KUKA robotic arms helped assemble consumer products.

What if a whole room became one always-on computer that everyone shares?

Could it feel like home, the way I imagined the Enterprise-D?

More about ACME LabClose ACME Lab

Co-founder + Head of Product · Google X · 2014–2015

Our mandate was a spatial OS for future robotics. The lab also needed credibility now, and a viable path from today to that future.

  1. Make the next step concrete.

    Research teams had their own priorities, and I had to influence them without relying on reporting authority.

    Senior Google executives touring the space were our immediate audience. I prioritized one physical walkthrough across X projects, bringing sensing, ambient displays, voice and robotics together.

    Robotics mandateLong-term ambitionSpatial OSA shared technical foundationExecutive walkthroughImmediate, concrete proof
  2. Build at the scale of a room.

    $20M
    internal funding, 2014
    4
    pilot retail stores, 2015

    The work began after a gaze-based Glass prototype reached Google’s leadership team (the L-Team). The lab’s sensor fusion combined far-field microphones, BLE beacons and LiDAR.

  3. Give applications a shared foundation.

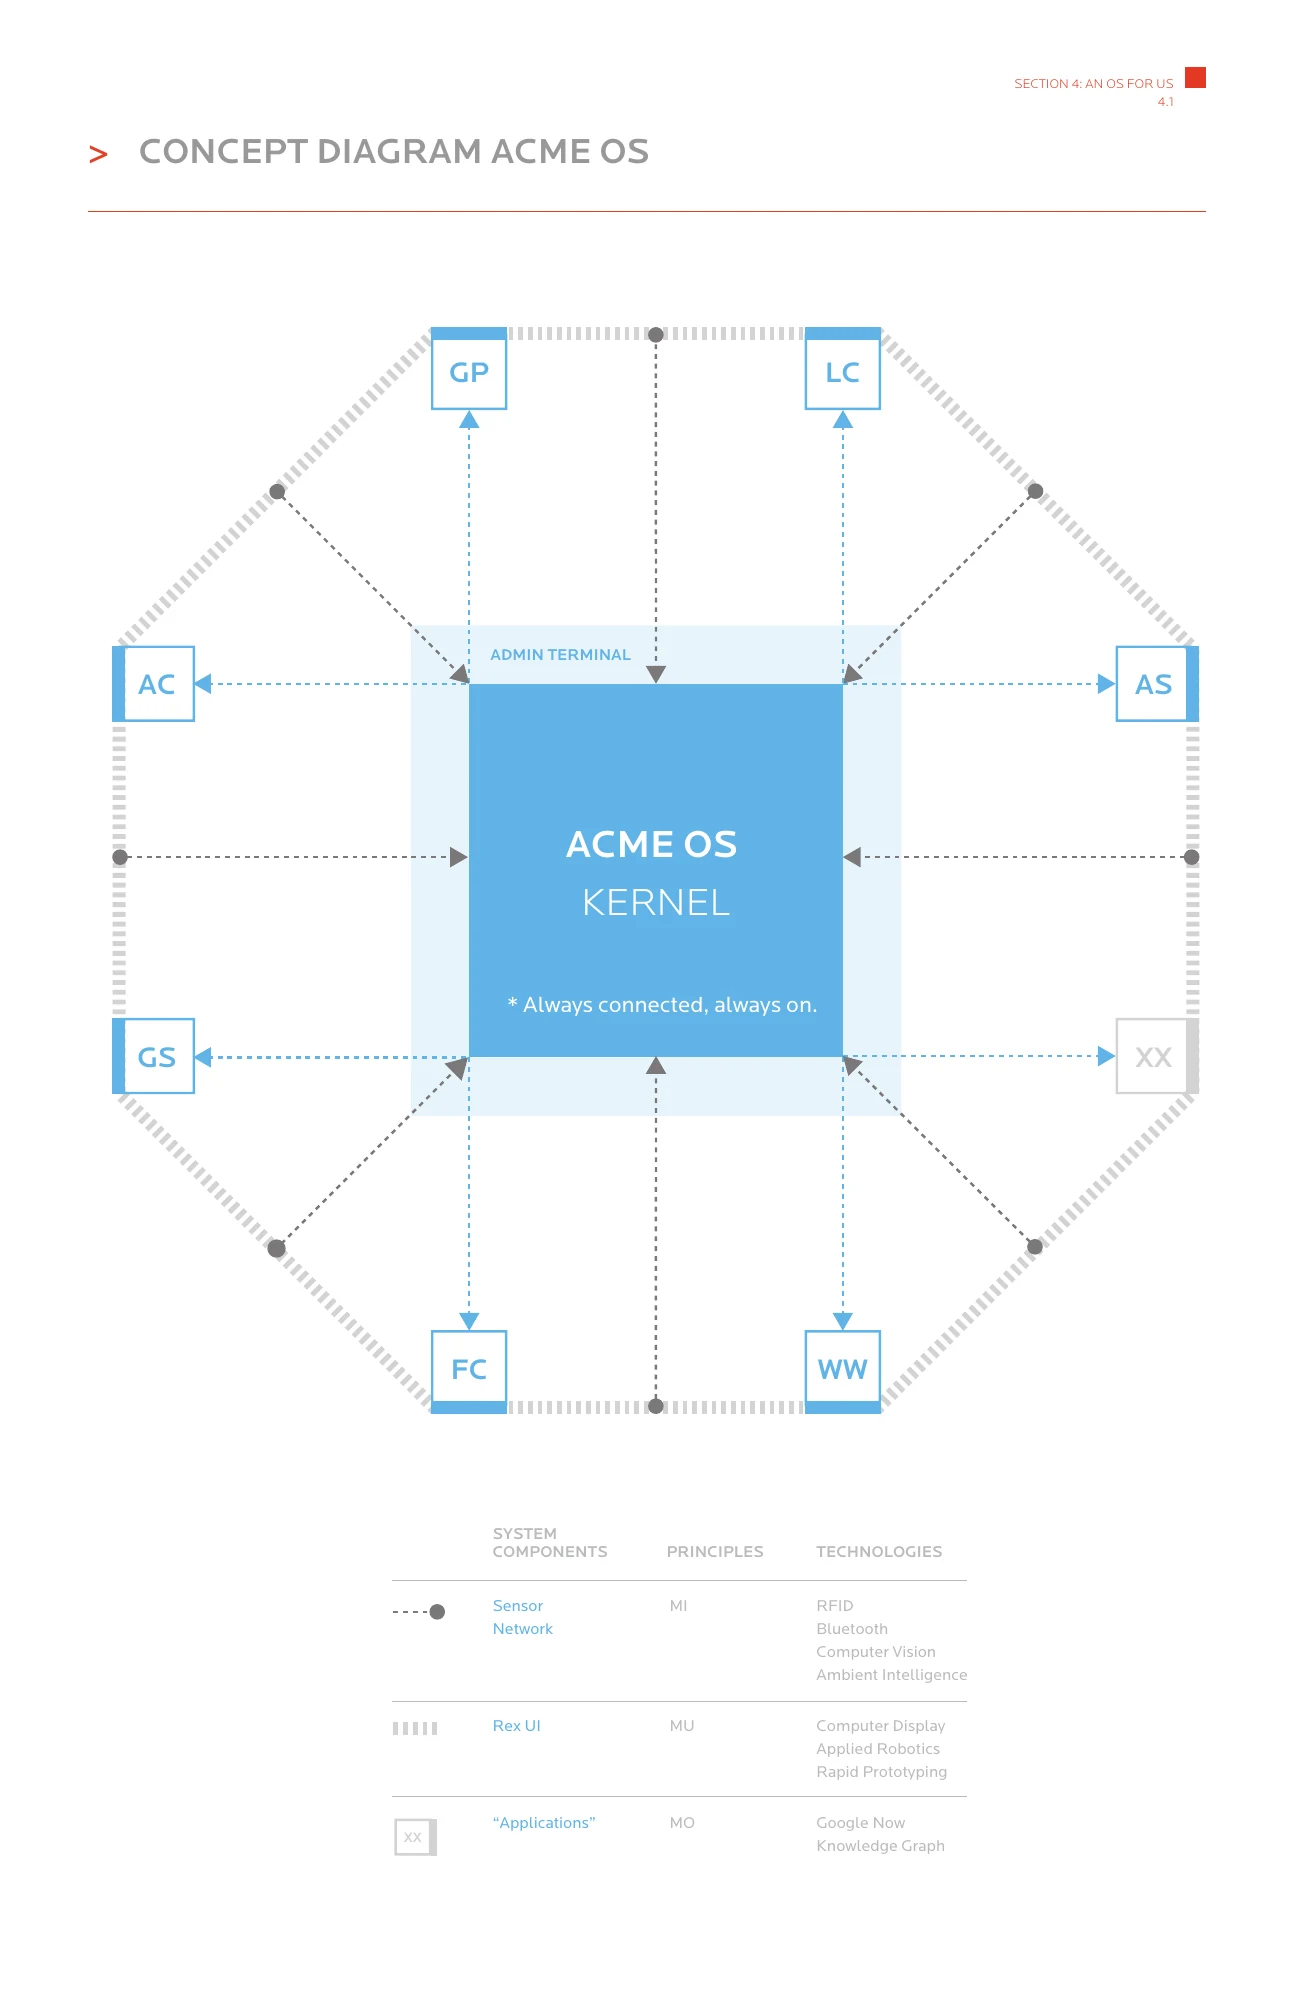
    The plan put hardware access in ACME OS, separate from the Rex applications. It staged infrastructure and sensor integration before application integration.

    Original ACME OS concept diagram: a central kernel and admin terminal connect to a sensor network, Rex interface and multiple applications.
    ACME OS / Rex concept architecture; development plan on p. 27. PDF p. 29. View original page

    The June 2014 drawings describe the proposal; the dot exhibit shows my account of the deployed lab.

  4. Keep personal information personal.

    The proposal reserved personal displays for private information, while walls and other shared surfaces supported collective experiences.

    ACME Lab09 artifacts

What Matters to People

Fear Less

Find your voice

My role: Design + creative lead

How can search, video, and touch help someone prepare to speak?

Can tech help us overcome our own fear?

More about Fear LessClose Fear Less

Global Head of Design + Creative · Google · 2013

  1. Let the human moment carry the story.

    A Nexus 7 helps a boy prepare for a classroom presentation. Then he has to face the room.

    Fear Less remains one of my favorite pieces of work at Google.

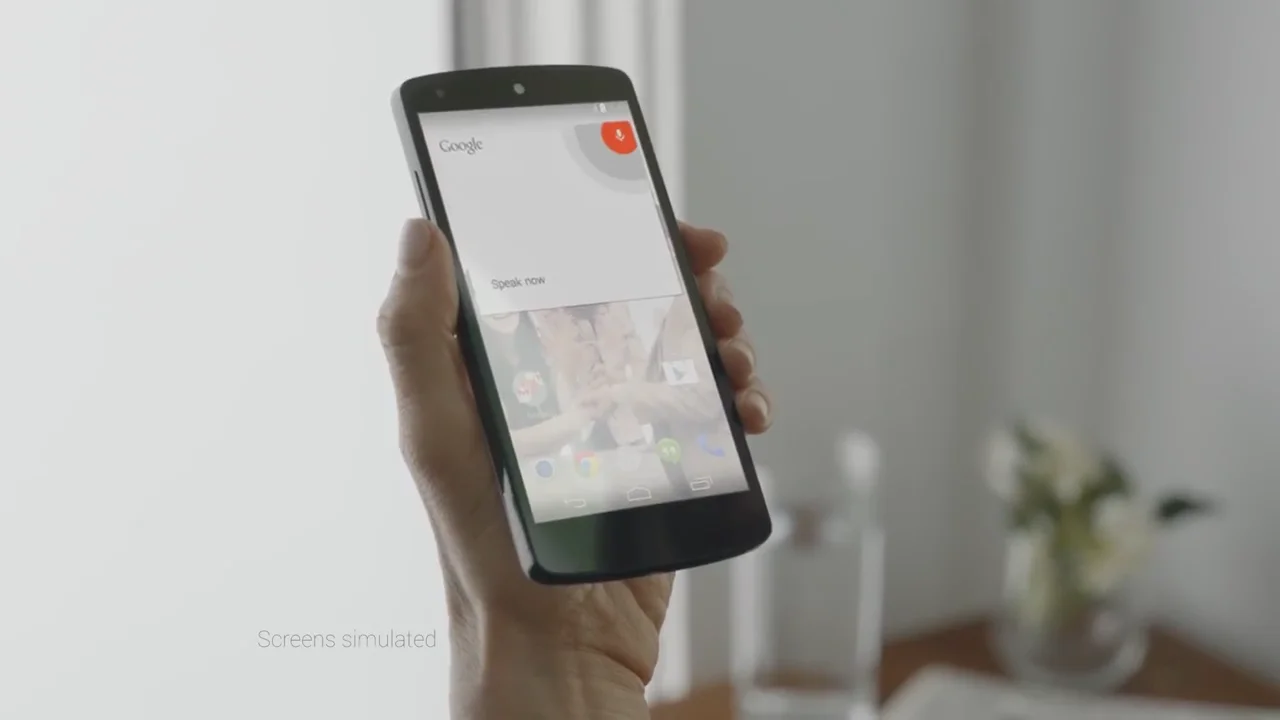
OK Google

Just say the word

My role: Design + creative lead

Can one spoken question show what voice search is capable of?

When will talking to my phone stop feeling weird?

More about OK GoogleClose OK Google

Global Head of Design + Creative · Google · 2013

  1. Show people how to begin.

    Saying “OK Google” shows the product and invites you to try it.

Scale Global Platform

Android & Nexus

Run Open, Run Free, Run Android

My role: Global head of design + creative Positioning → launch

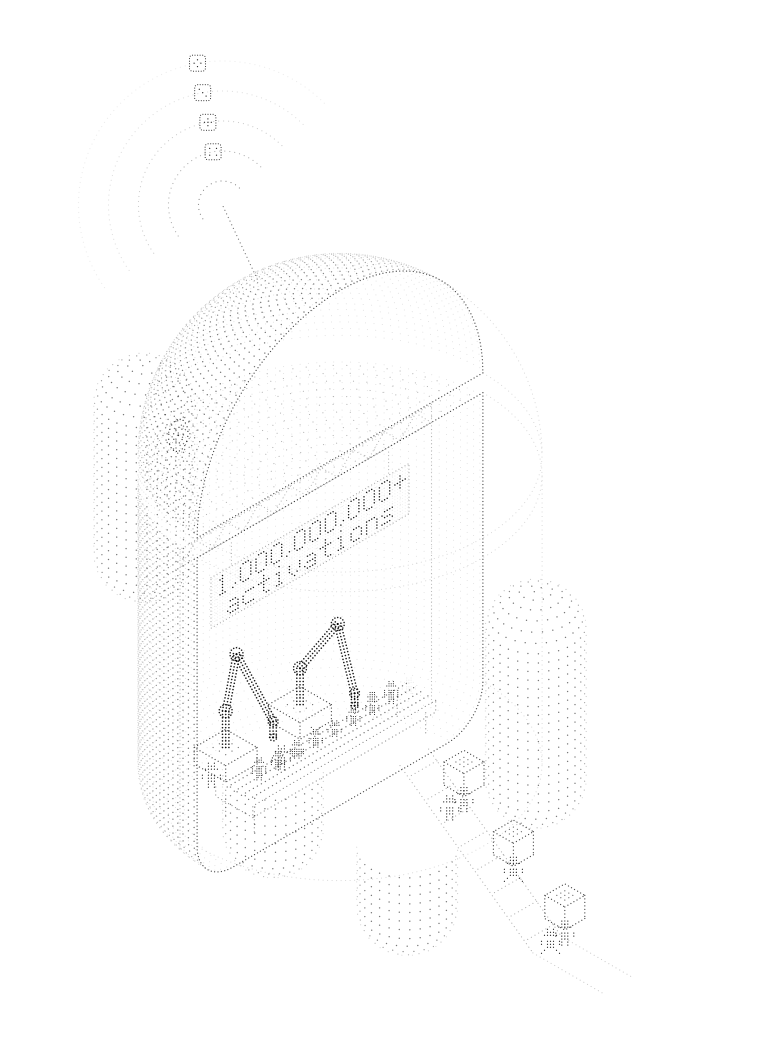
1B+ cumulative device activations

Can companies that want different things still build one platform together?

Would people be proud to make it their own?

More about Android & NexusClose Android & Nexus

Global Head of Design + Creative · Google · 2009–2014 · HR title: Senior Product Marketing Manager

Manufacturers wanted differentiation. Carriers wanted their own customer relationships. Developers needed applications to work across devices. My job was to help make openness and choice a proposition they shared, while leaving room for their differences.

  1. Keep the boundaries clear.

    I co-architected Android’s brand doctrine around openness and choice: different devices, price points and routes to market within a recognizable platform.

    Open-source software, compatibility requirements, separately licensed Google services and brand identity each did a different job. Compatibility rested on engineering requirements and testing; marketing had to explain what it promised.

    Different devices, price points and routes to market.One compatibility baseline · requirements and testing

    Android could be used without Google’s apps or distribution. The robot could be adapted under CC BY 3.0; the Android wordmark and Google trademarks followed separate rules.

    A shared symbol, made their own.

    Bugdroid · CC BY 3.0 · adapted

    WordmarkTrademarksSeparate rules
  2. Give partners a framework they can use.

    I led development of brand guidance, co-marketing assets and retail materials that country teams could adapt. With agency partners, we made the shared identity practical for local launches.

    A common framework for different campaigns.Brand guidance · co-marketing assets · retail materials

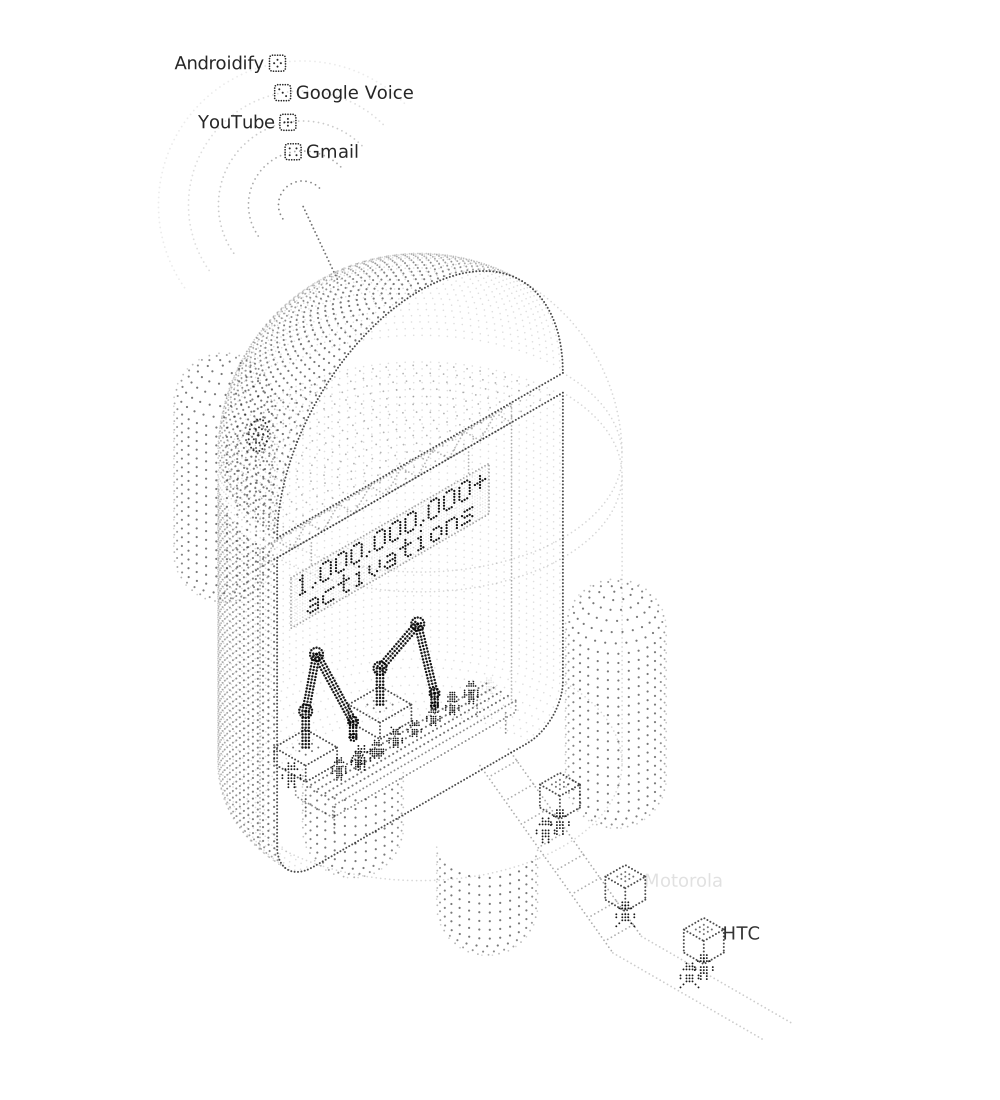
    DROID and Galaxy could retain distinct identities. At Mobile World Congress in 2012, more than 100 devices appeared on a conveyor-belt display alongside developer app pods.

    Interpretive comparisons of the linked launch records. Androidify creator credit: Larva Labs ↗. These are public ecosystem examples, not a list of campaigns attributed to me individually.
  3. Help developers build, then be seen.

    I directed design and delivery work on the Android Developer portal, SDK documentation and technical videos. We paired those resources with device distribution and co-marketing; through Studio G, we helped developers make launch films.

    1. BuildPortal · SDK documentation · technical films
    2. ReachCo-marketing · launch films

    For Google I/O, I translated platform changes into developer messaging. One public example of a platform change: in December 2012, the new Maps API reached compatible devices running Android 2.2 and newer through Google Play services.

    Google for Developers · keynote archive.
  4. Make a reference. Learn how people buy it.

    I led global brand and creative for Nexus, including “Pure Google” positioning. Nexus gave hardware, Android and Google services a reference experience, without asking every manufacturer to copy it.

    The first web store exposed a different problem: people wanted to try a phone and choose a service plan.

    1. Nexus One web store
    2. Broader retail model announced

    Google introduced the Nexus One web store in January 2010. In May, it announced a broader retail model after the online channel remained niche. The distribution decision is documented in Google’s public account; my remit was Nexus brand and creative.

What the ecosystem reached.

81.2%
of worldwide smartphone shipments in 2014

Strategy Analytics · calendar-year estimate, published January 2015

These were shared ecosystem outcomes. My contribution was the brand doctrine and repeatable programs behind Nexus, partner marketing and developer communication.

Ecosystem milestones

The activation history counts cumulative devices. The 2014 share estimates a year’s smartphone shipments. They describe different measures of the ecosystem, not one continuous series.

Cumulative Android device activations1 dot = 10 million
100MMay 2011300M+February 2012400M+June 2012750M+March 2013900MMay 20131B+September 2013
100M
300M+
400M+
750M+
900M
1B+
Six reported milestones, unevenly spaced. A + marks a lower bound, so the dots show that threshold rather than an exact total. Activations count devices, not people.

By October 2014, the wider Android brand expressed the principle as “Be together. Not the same.”

One platform. More ways to live.

A shared foundation lets different companies build for very different lives.

My work: brand, partner programs and developer communication, 2009–2014. The examples below show the ecosystem continuing in 2025–2026.

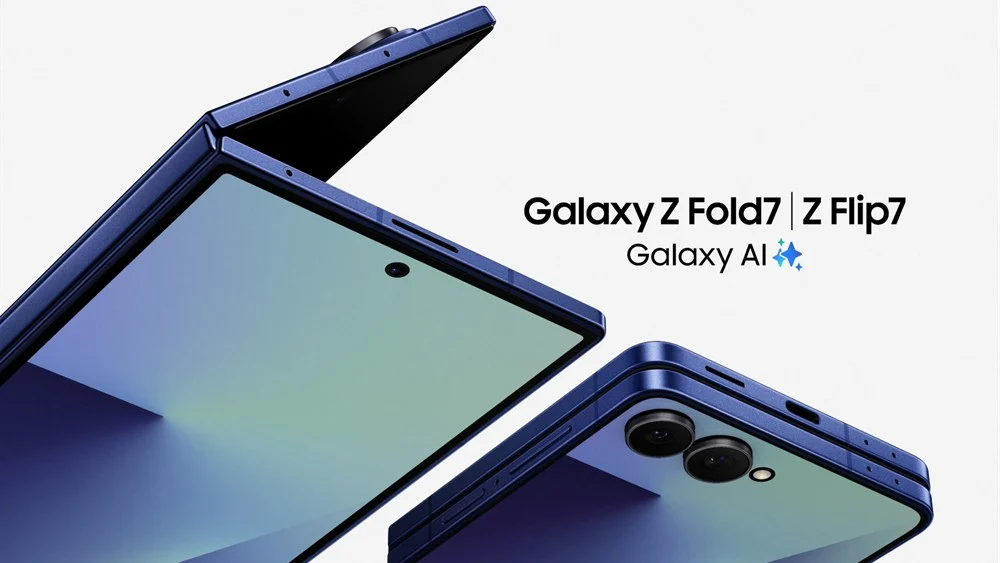
Samsung's 2025 launch image shows the Galaxy Z Fold7 and Z Flip7 in blue, opened at different angles.
A workspace that folds.Samsung Galaxy Z Fold7 + Z Flip7 · 2025
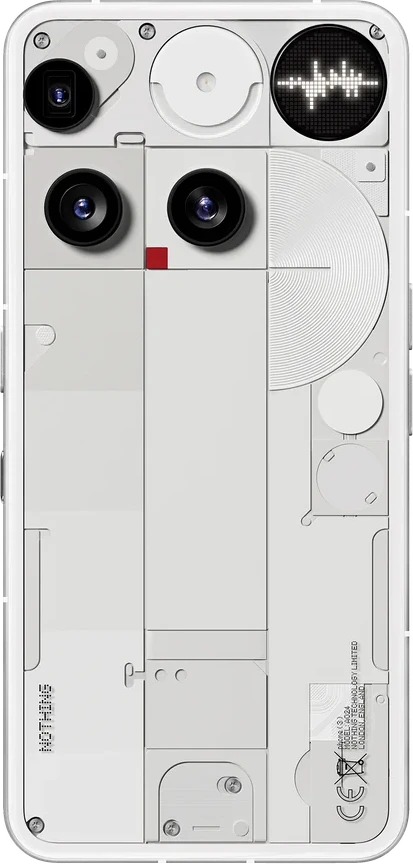
The white Nothing Phone (3), with its distinct circular camera layout and Glyph Matrix on the rear.
A different kind of phone.Nothing Phone (3) · 2025
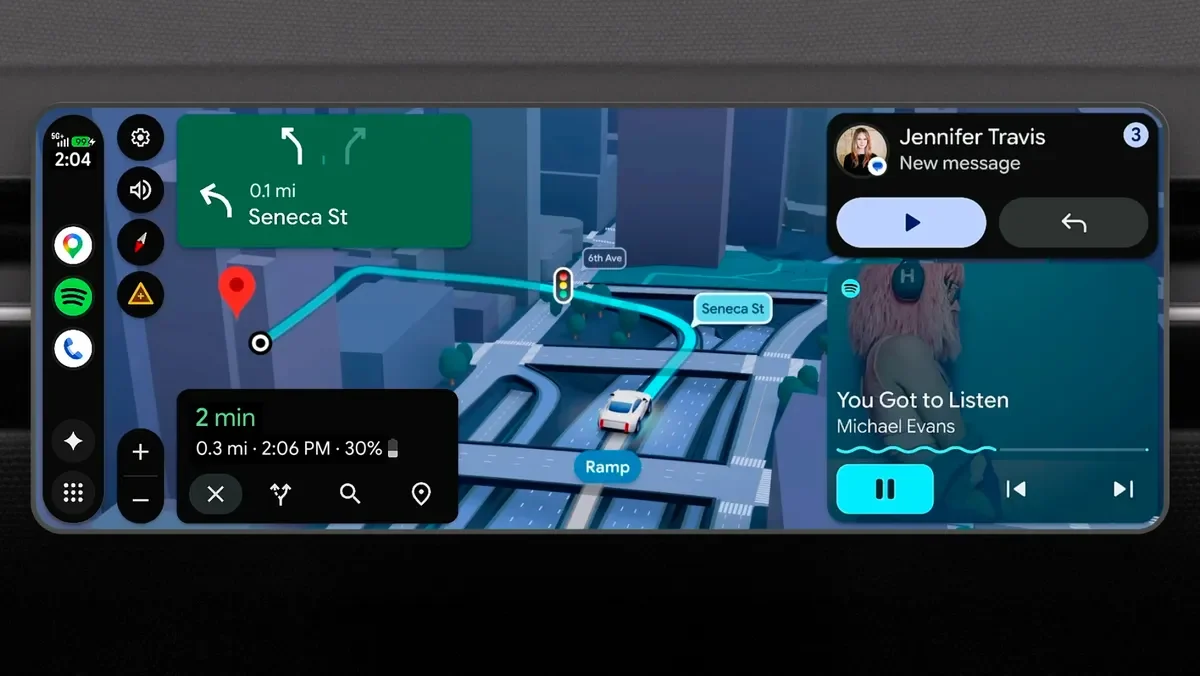
Google's rendering of its 2026 Android Auto driving interface on an in-car display.
The next turn, on the dashboard.Android Auto · 2026
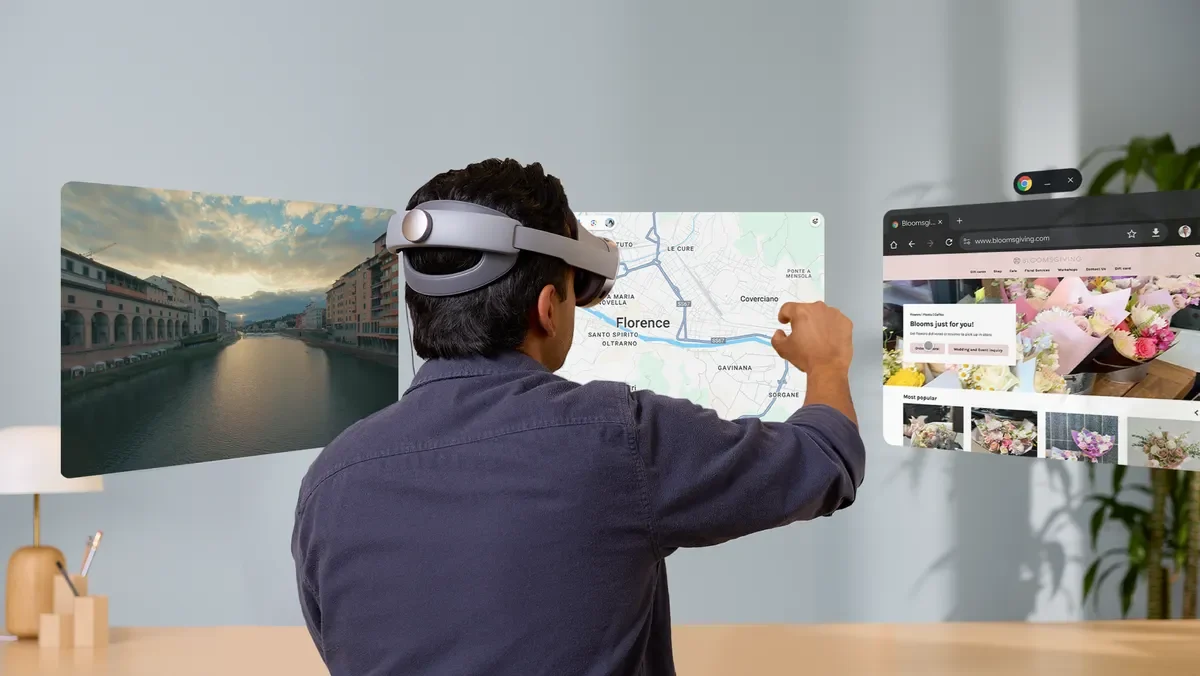
A person wearing Galaxy XR views a spatial workspace with video, Maps and a browser.
A canvas beyond the screen.Samsung Galaxy XR · 2025
Reported active Android devices
2B
3B+

Announcement snapshots; the later figure is a lower bound.

Google · May 2017Google · May 2025 · 190+ countries

Worldwide mobile web usage

72.36% Android

Observed web usage, not device sales or installed base.

Statcounter · October 2026
Openness creates different relationships.
Android devices

Samsung, Nothing and other makers build distinct products on Android.

SamsungNothing
Derived platforms

Amazon’s Fire OS is an Android fork with Amazon services. Some newer Fire TV devices use Vega OS instead.

Amazon · Fire OS / Vega OS
Connections beyond Android

Microsoft Phone Link brings supported Android phone features into Windows.

Microsoft · Phone Link

The question I bring to AI platforms now is where shared guarantees should end and builder freedom should begin.

Sources

Role and program descriptions are my account. The public records document the platform, launches and ecosystem measures.

Android robot adapted from work created and shared by Google, used under CC BY 3.0.

Explore the public launch archive

A Little Further Out

Rocket

100,000 feet closer to the Kármán line

My role: Google team lead AeroPac

What does rocket science take: aero, propellant, stability?

What's it like out in the Black Rock Desert with rocket nerds?

More about RocketClose Rocket

Google Team Lead · 2012

  1. Carry curiosity through the launch.

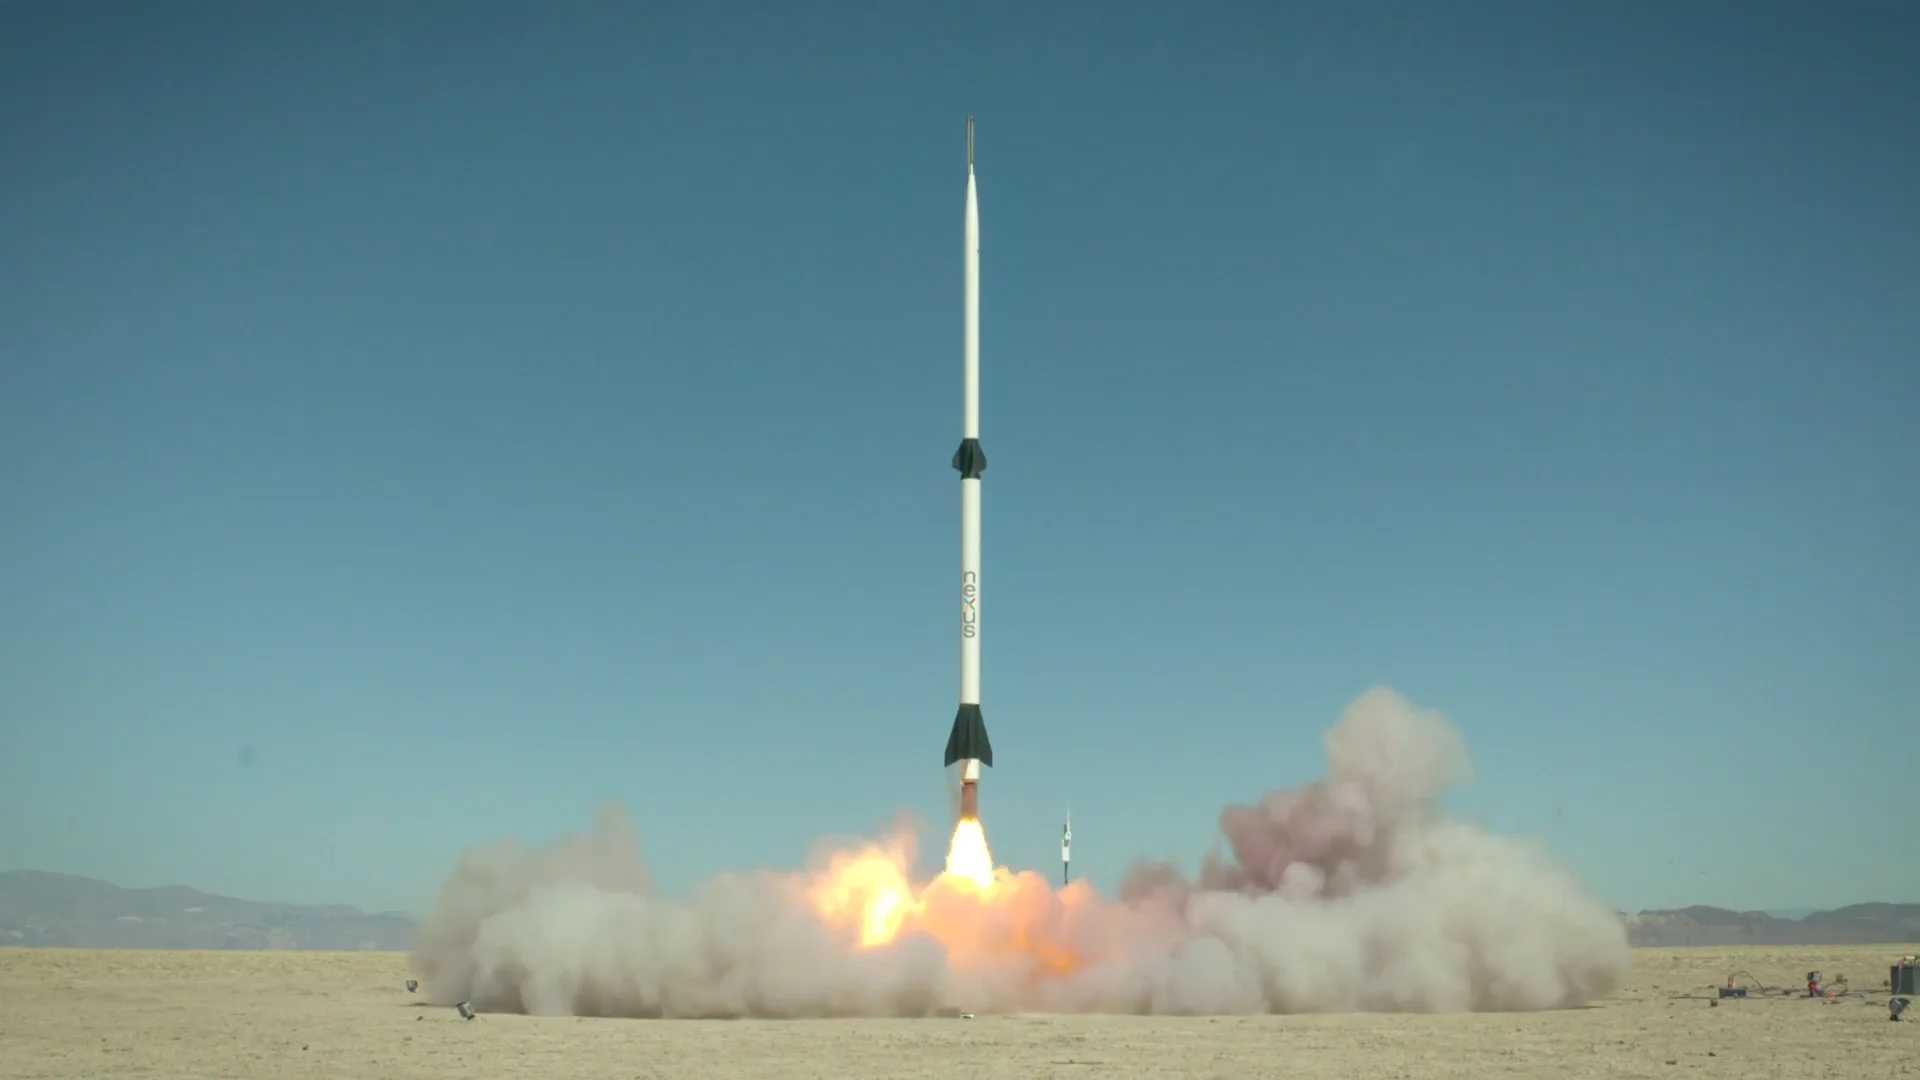
    104,659 ft
    altitude reached

    John Carmack Prize

NASA

Space, the final frontier…

My role: Initiative co-lead Google × NASA

Can a smartphone help steer a robot in microgravity?

How does it feel to be at the Kennedy Space Center?

More about NASAClose NASA

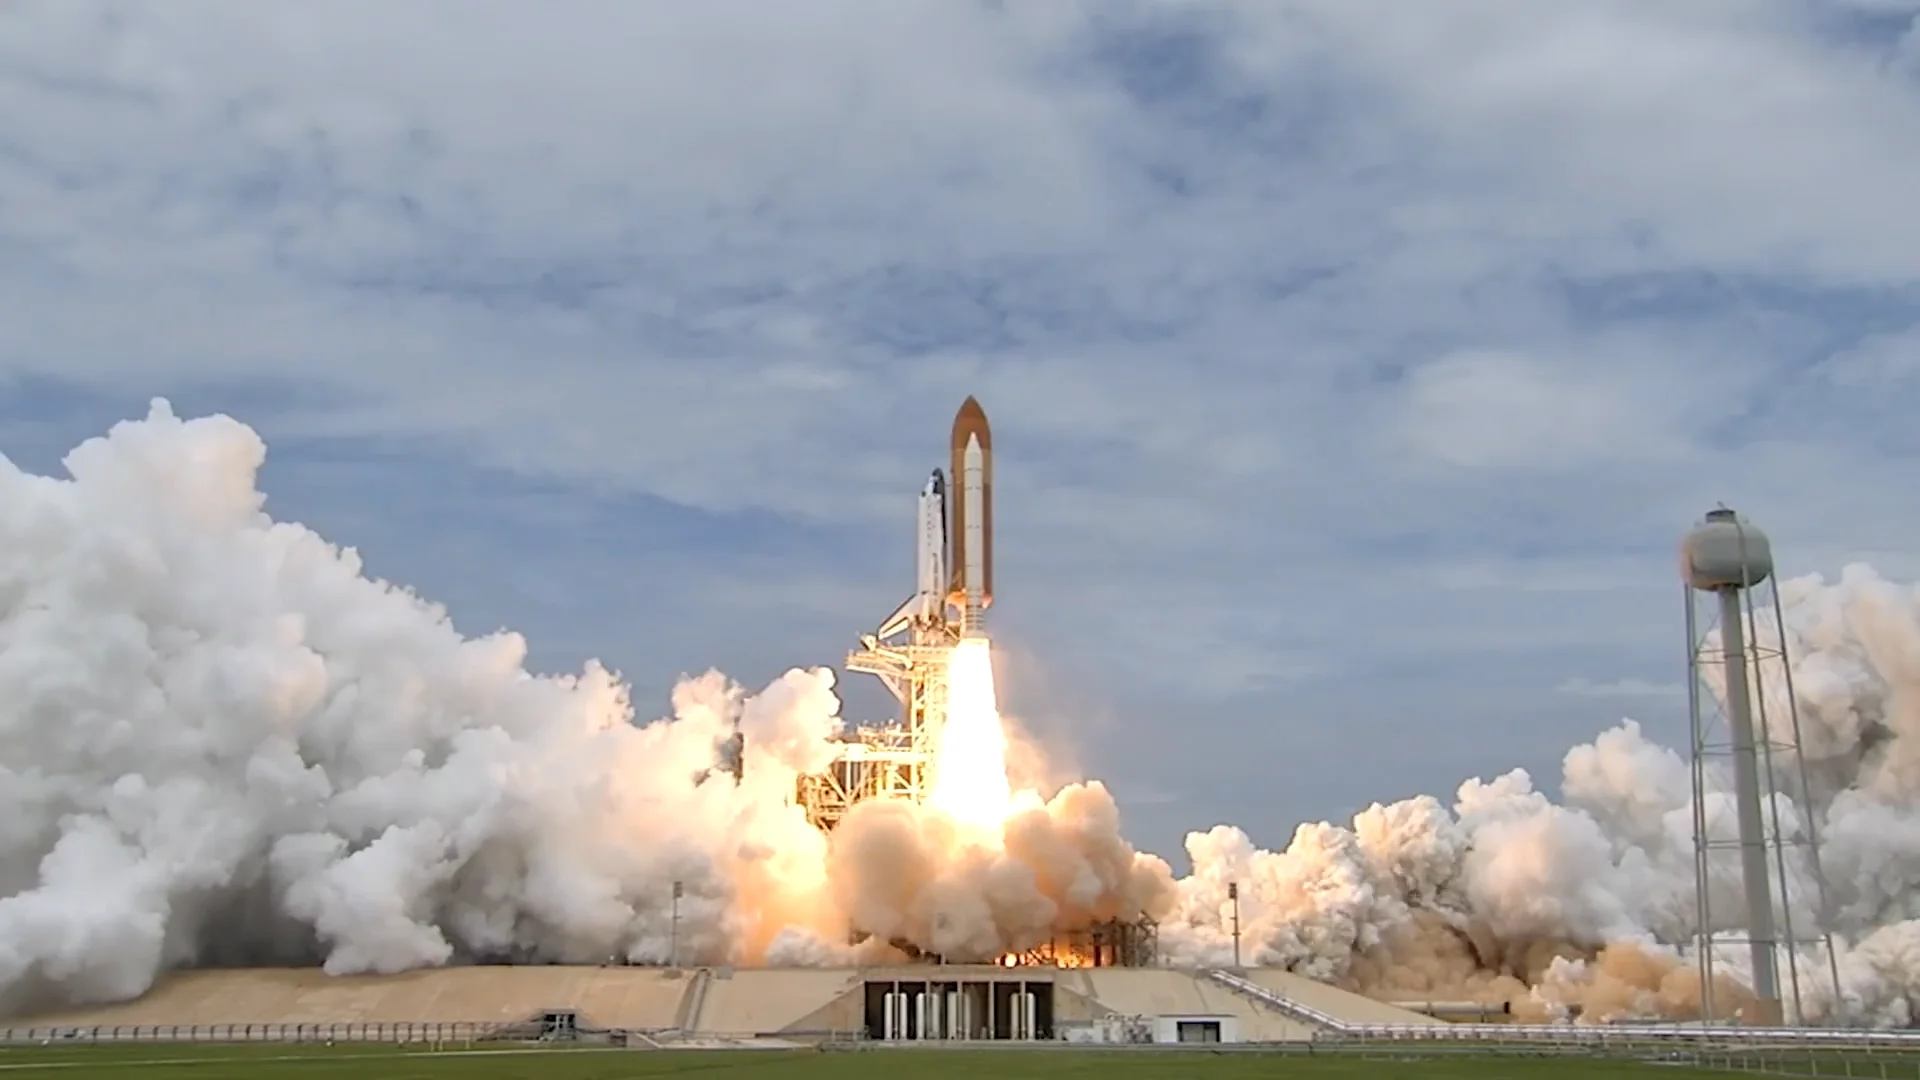
Google · Android + Nexus aboard Space Shuttle Atlantis · 2011

  1. Extend the robot with the phone.

    1. Nexus SCameras, sensors, computing power
    2. MIT SPHERESAn existing free-flying robot
  2. Take the experiment into orbit.

    I worked on Android in Space during my 20% time at Google.

    1. Atlantis · STS-135Two Nexus S phones · 2011
    2. International Space Station

Still tinkering

Some things you never outgrow

My role: Personal exploration Since 2005

When a machine can see, reason, and move, what makes us different?

Where do we go next?

More about Still tinkeringClose Still tinkering

Always up to no Good · Since 2005

  1. Keep the workbench record.

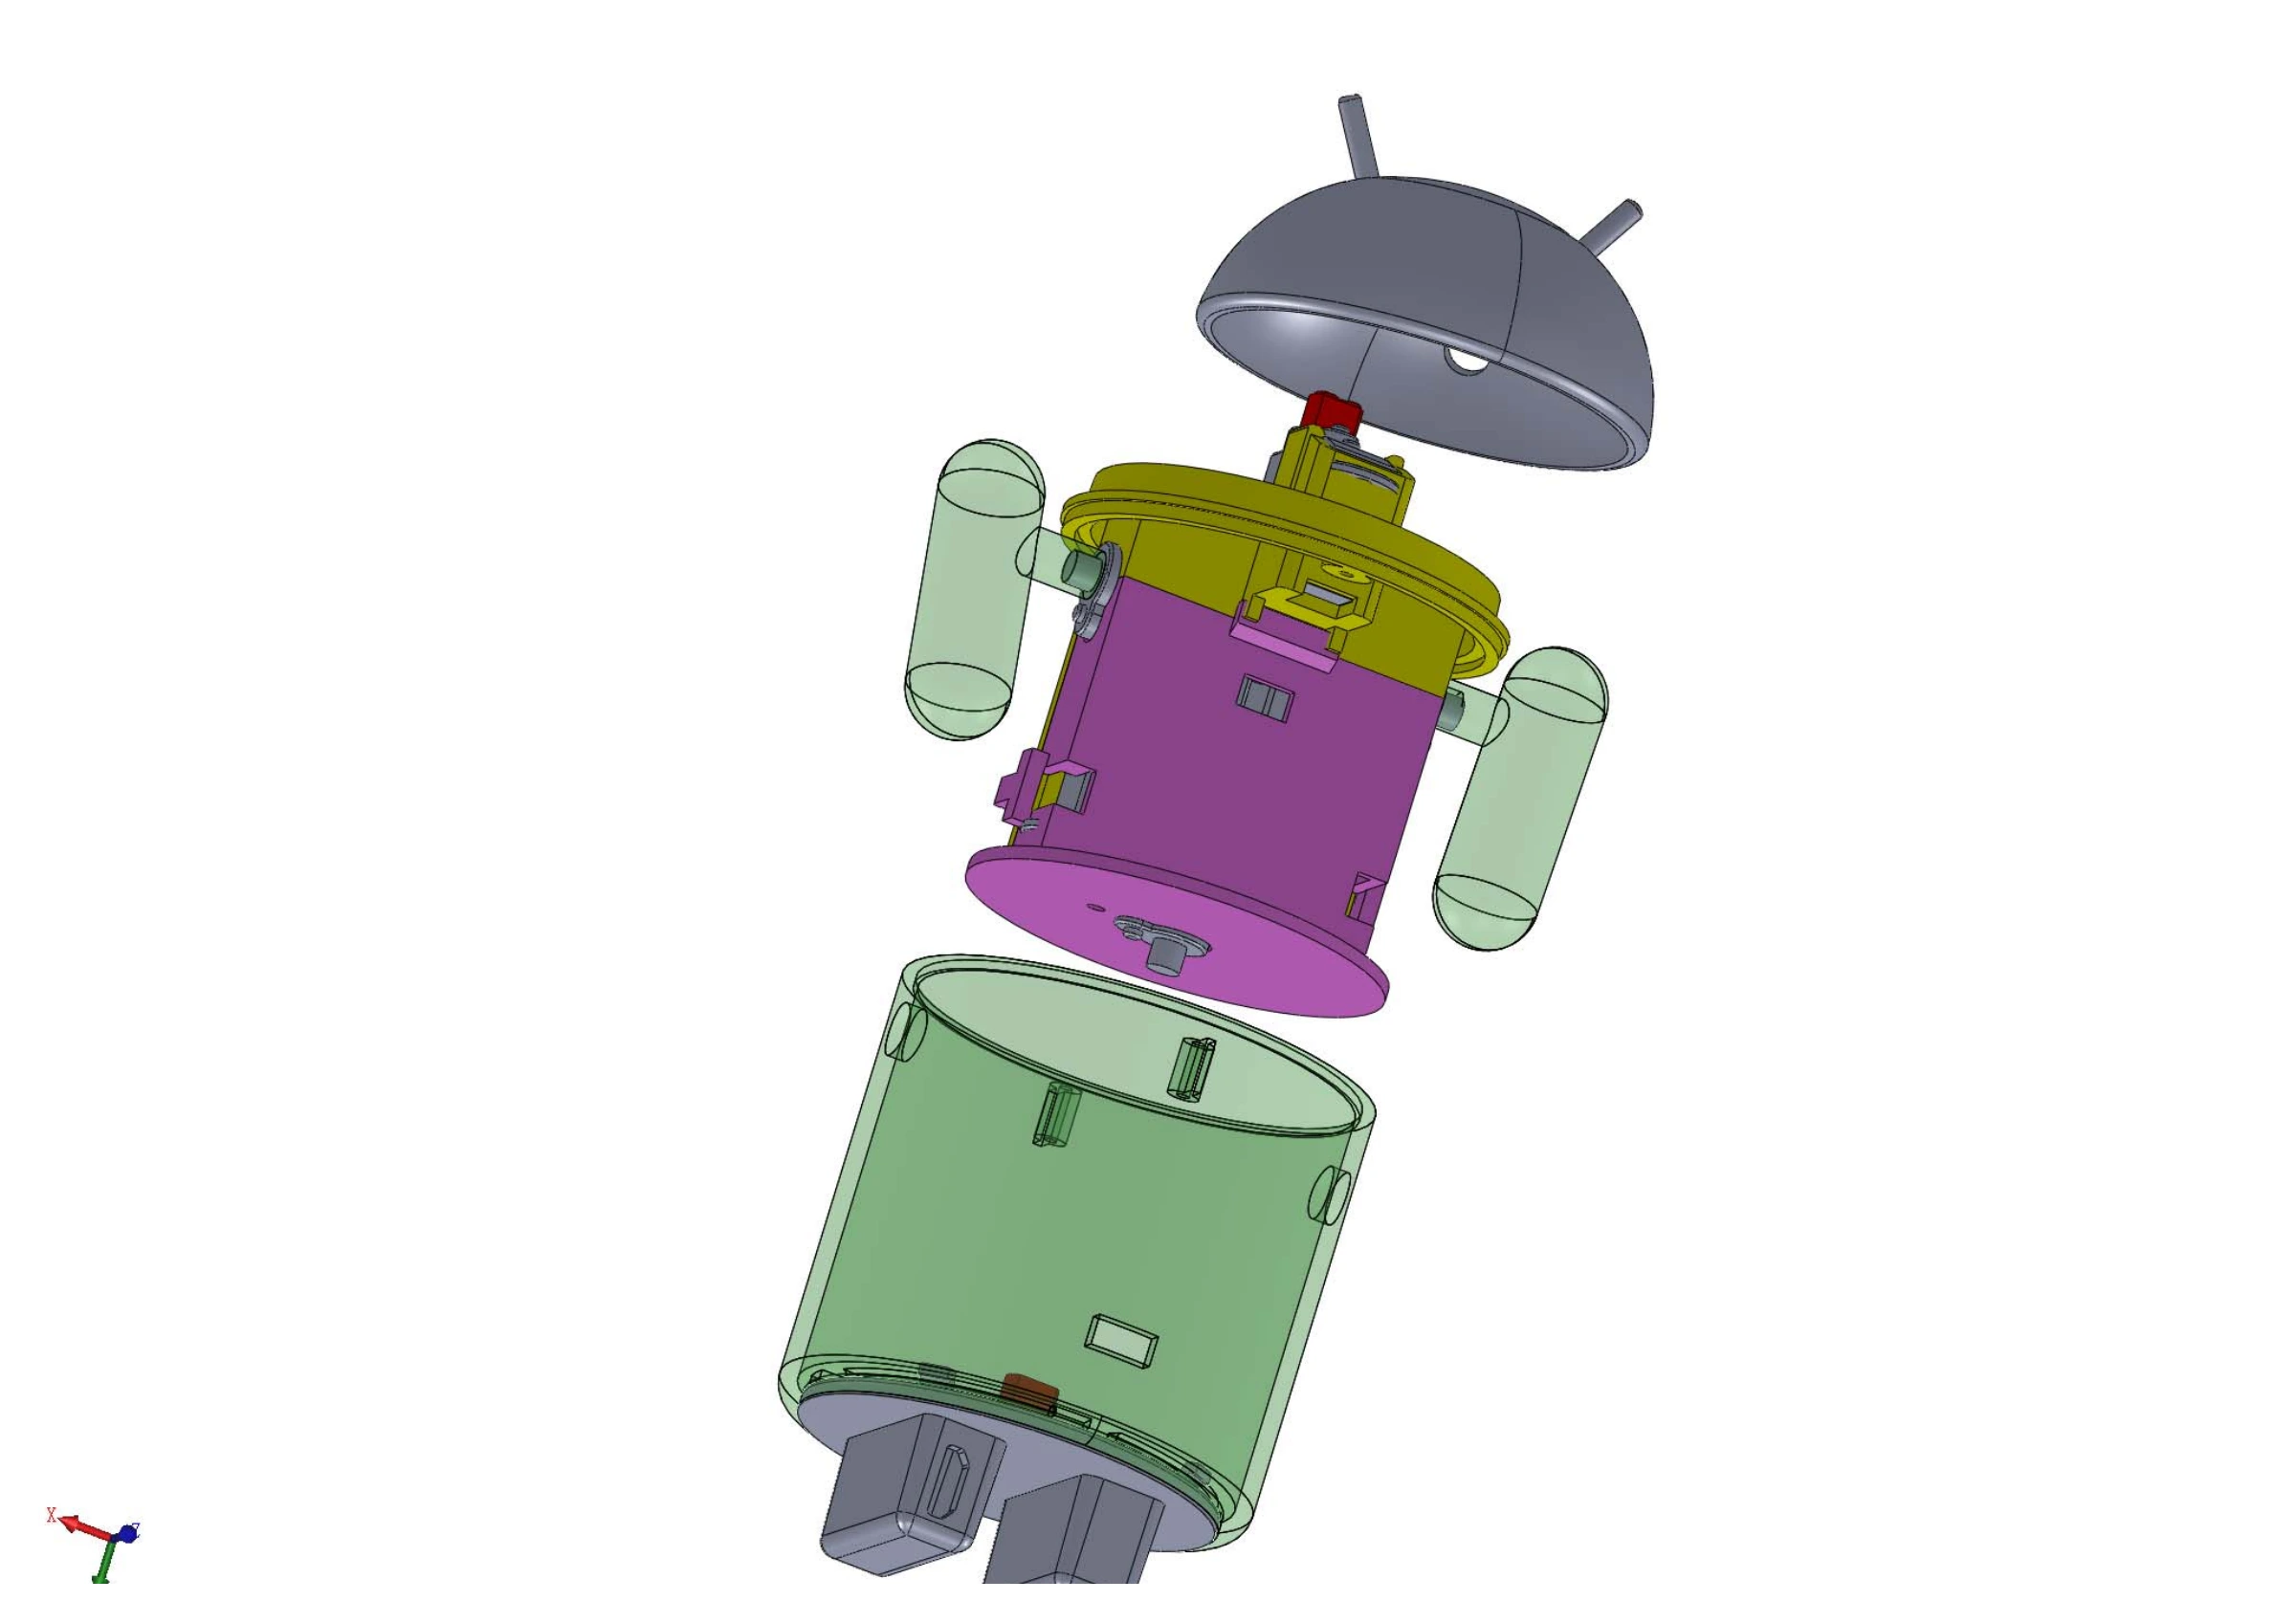
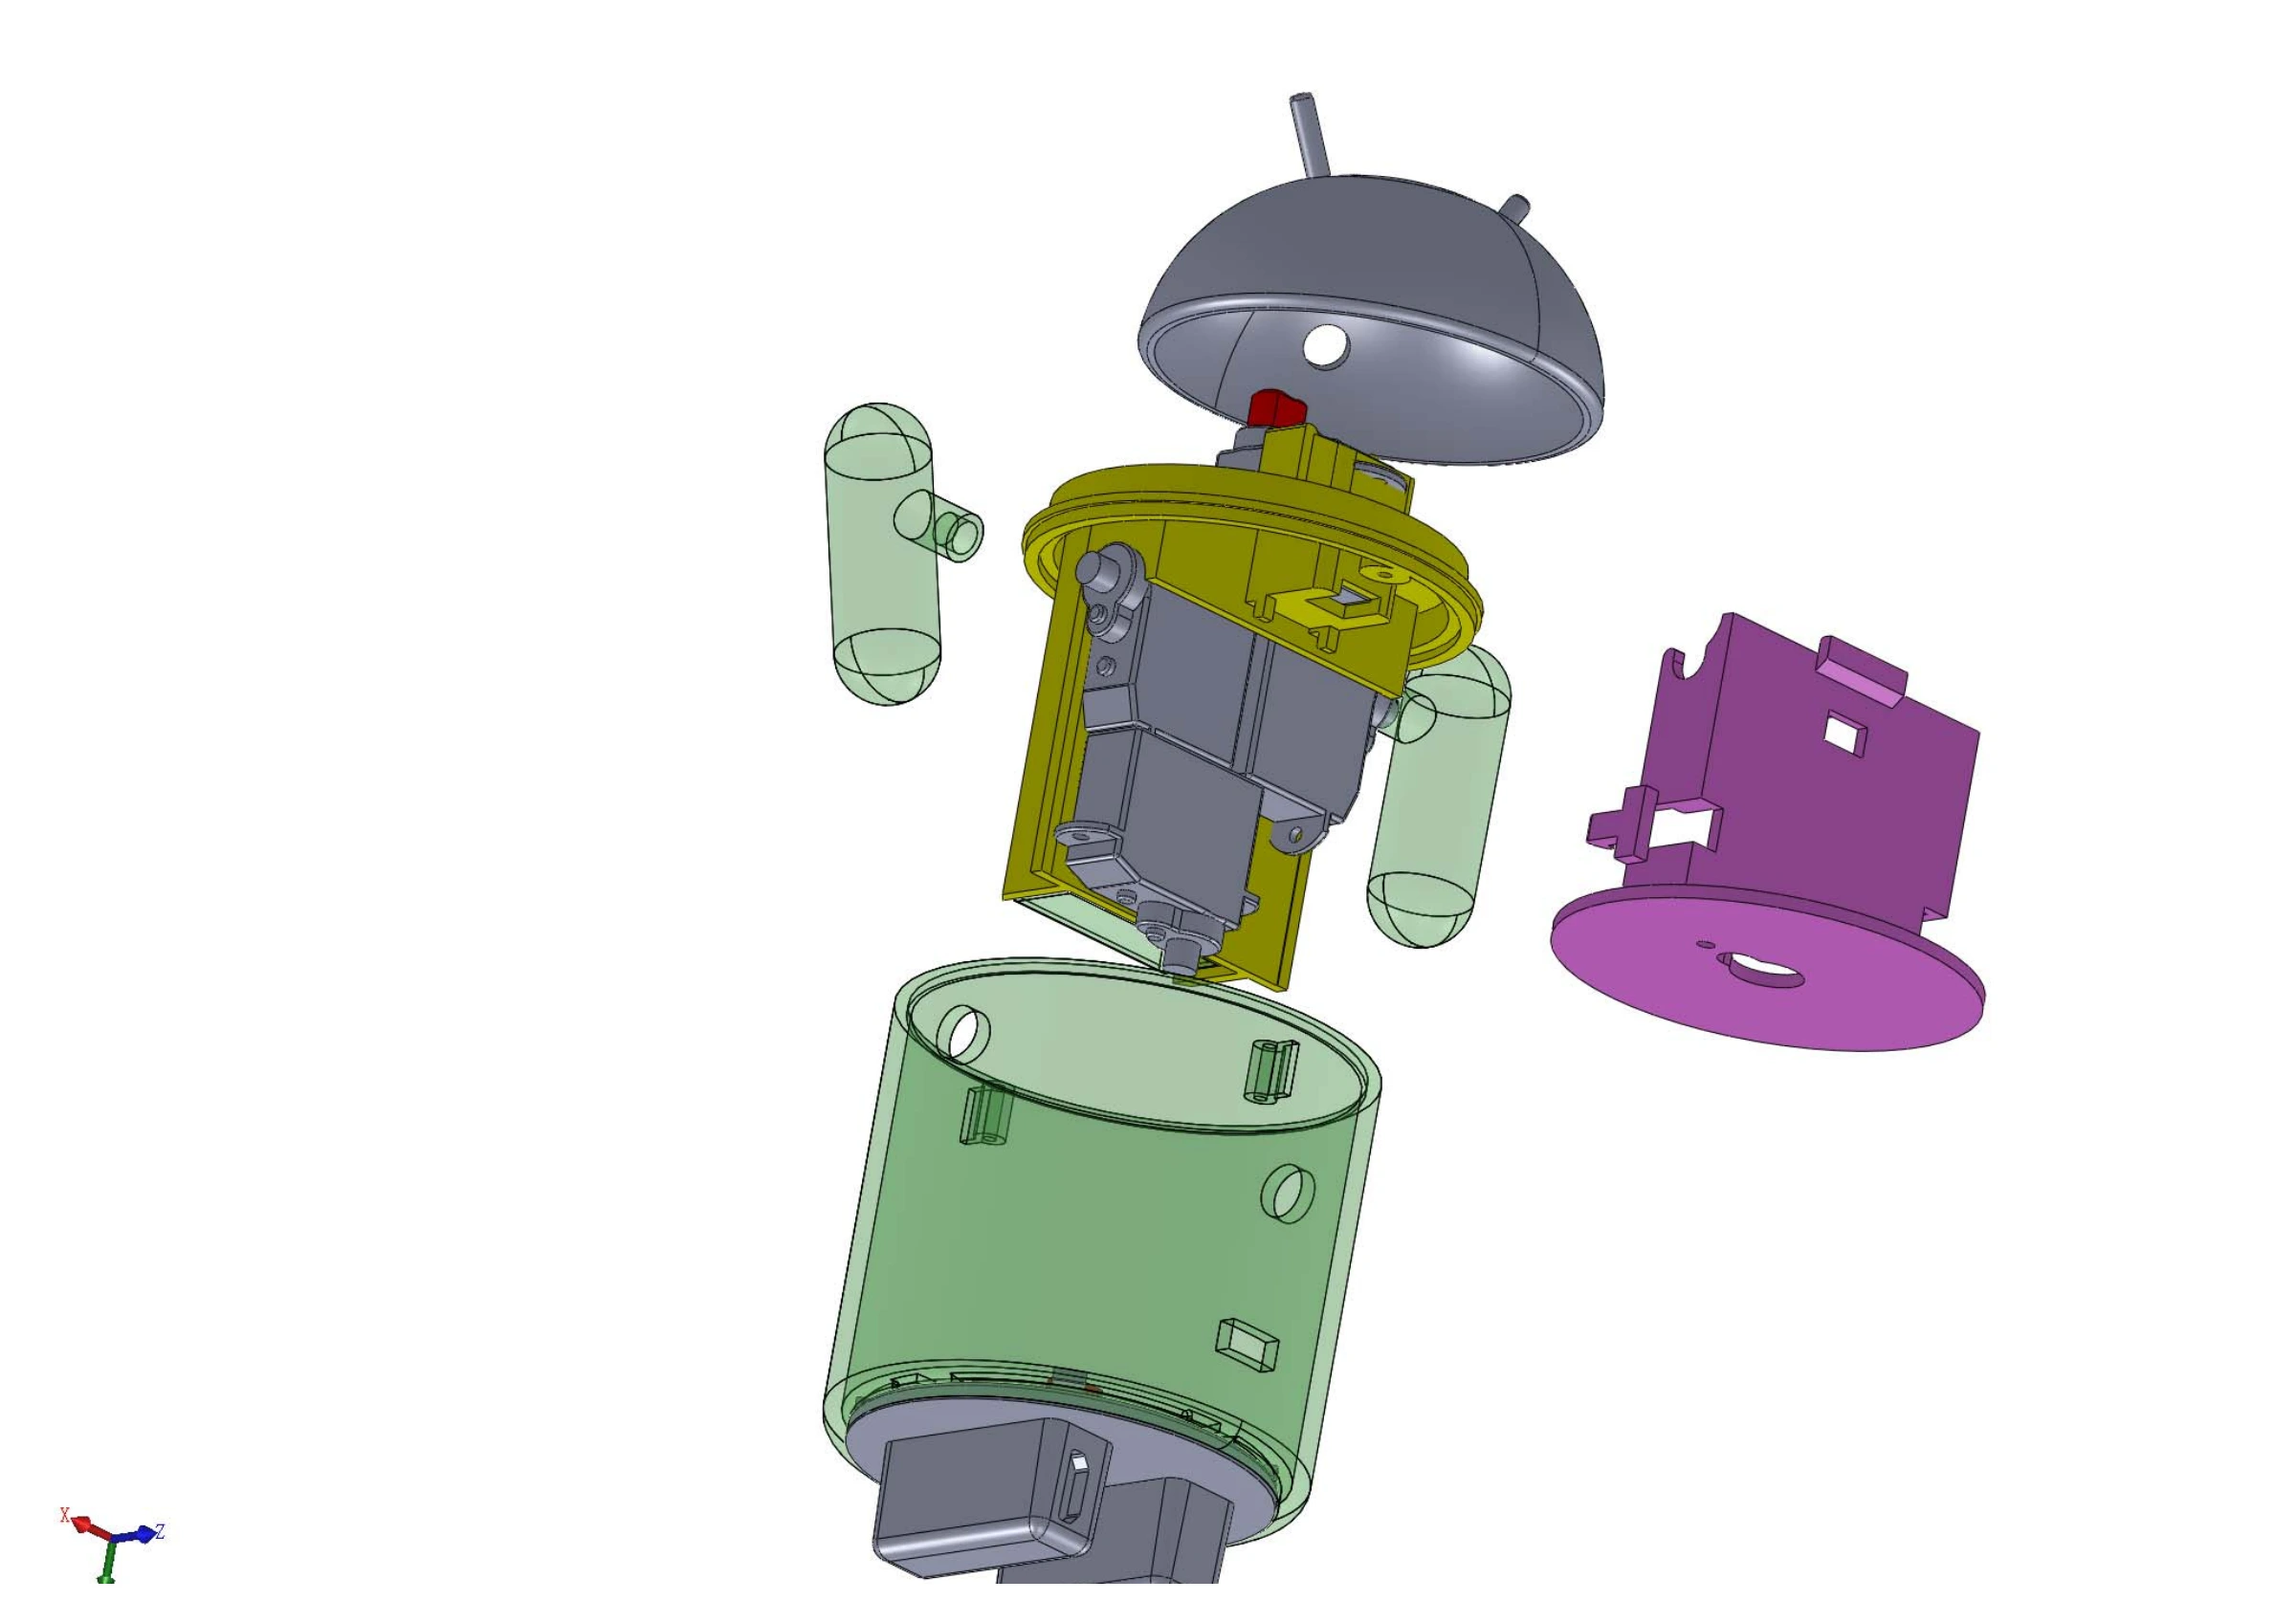
    Engineering drawings and workshop archive.
    An exploded CAD assembly separates the Android shell, internal carrier, head and arms. From the supplied toy-design archive.
    Inside the AndroidOriginal PDF
    The internal mechanism with its carrier opened out, showing how the components fit inside the Android body.
    Making room for movementOriginal PDF
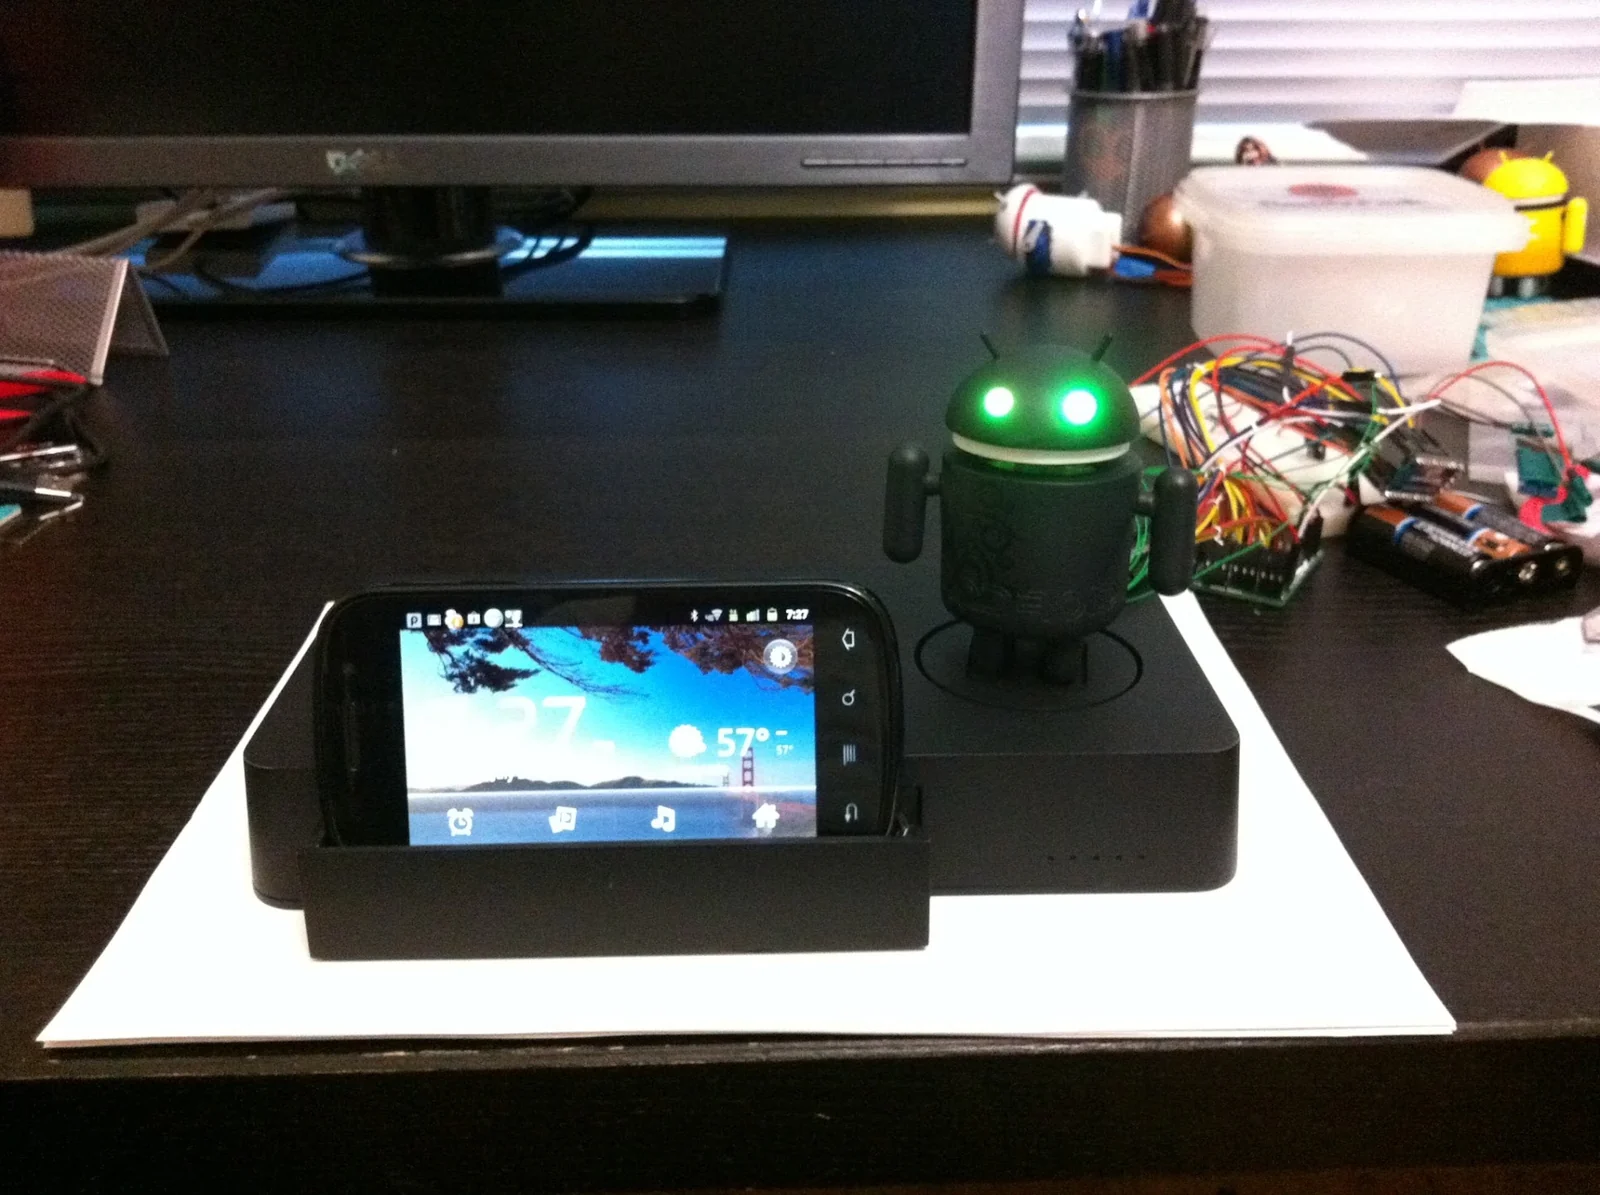
    An Android robot prototype beside a docked Nexus phone, with its wiring still exposed.
    A phone meets a robot
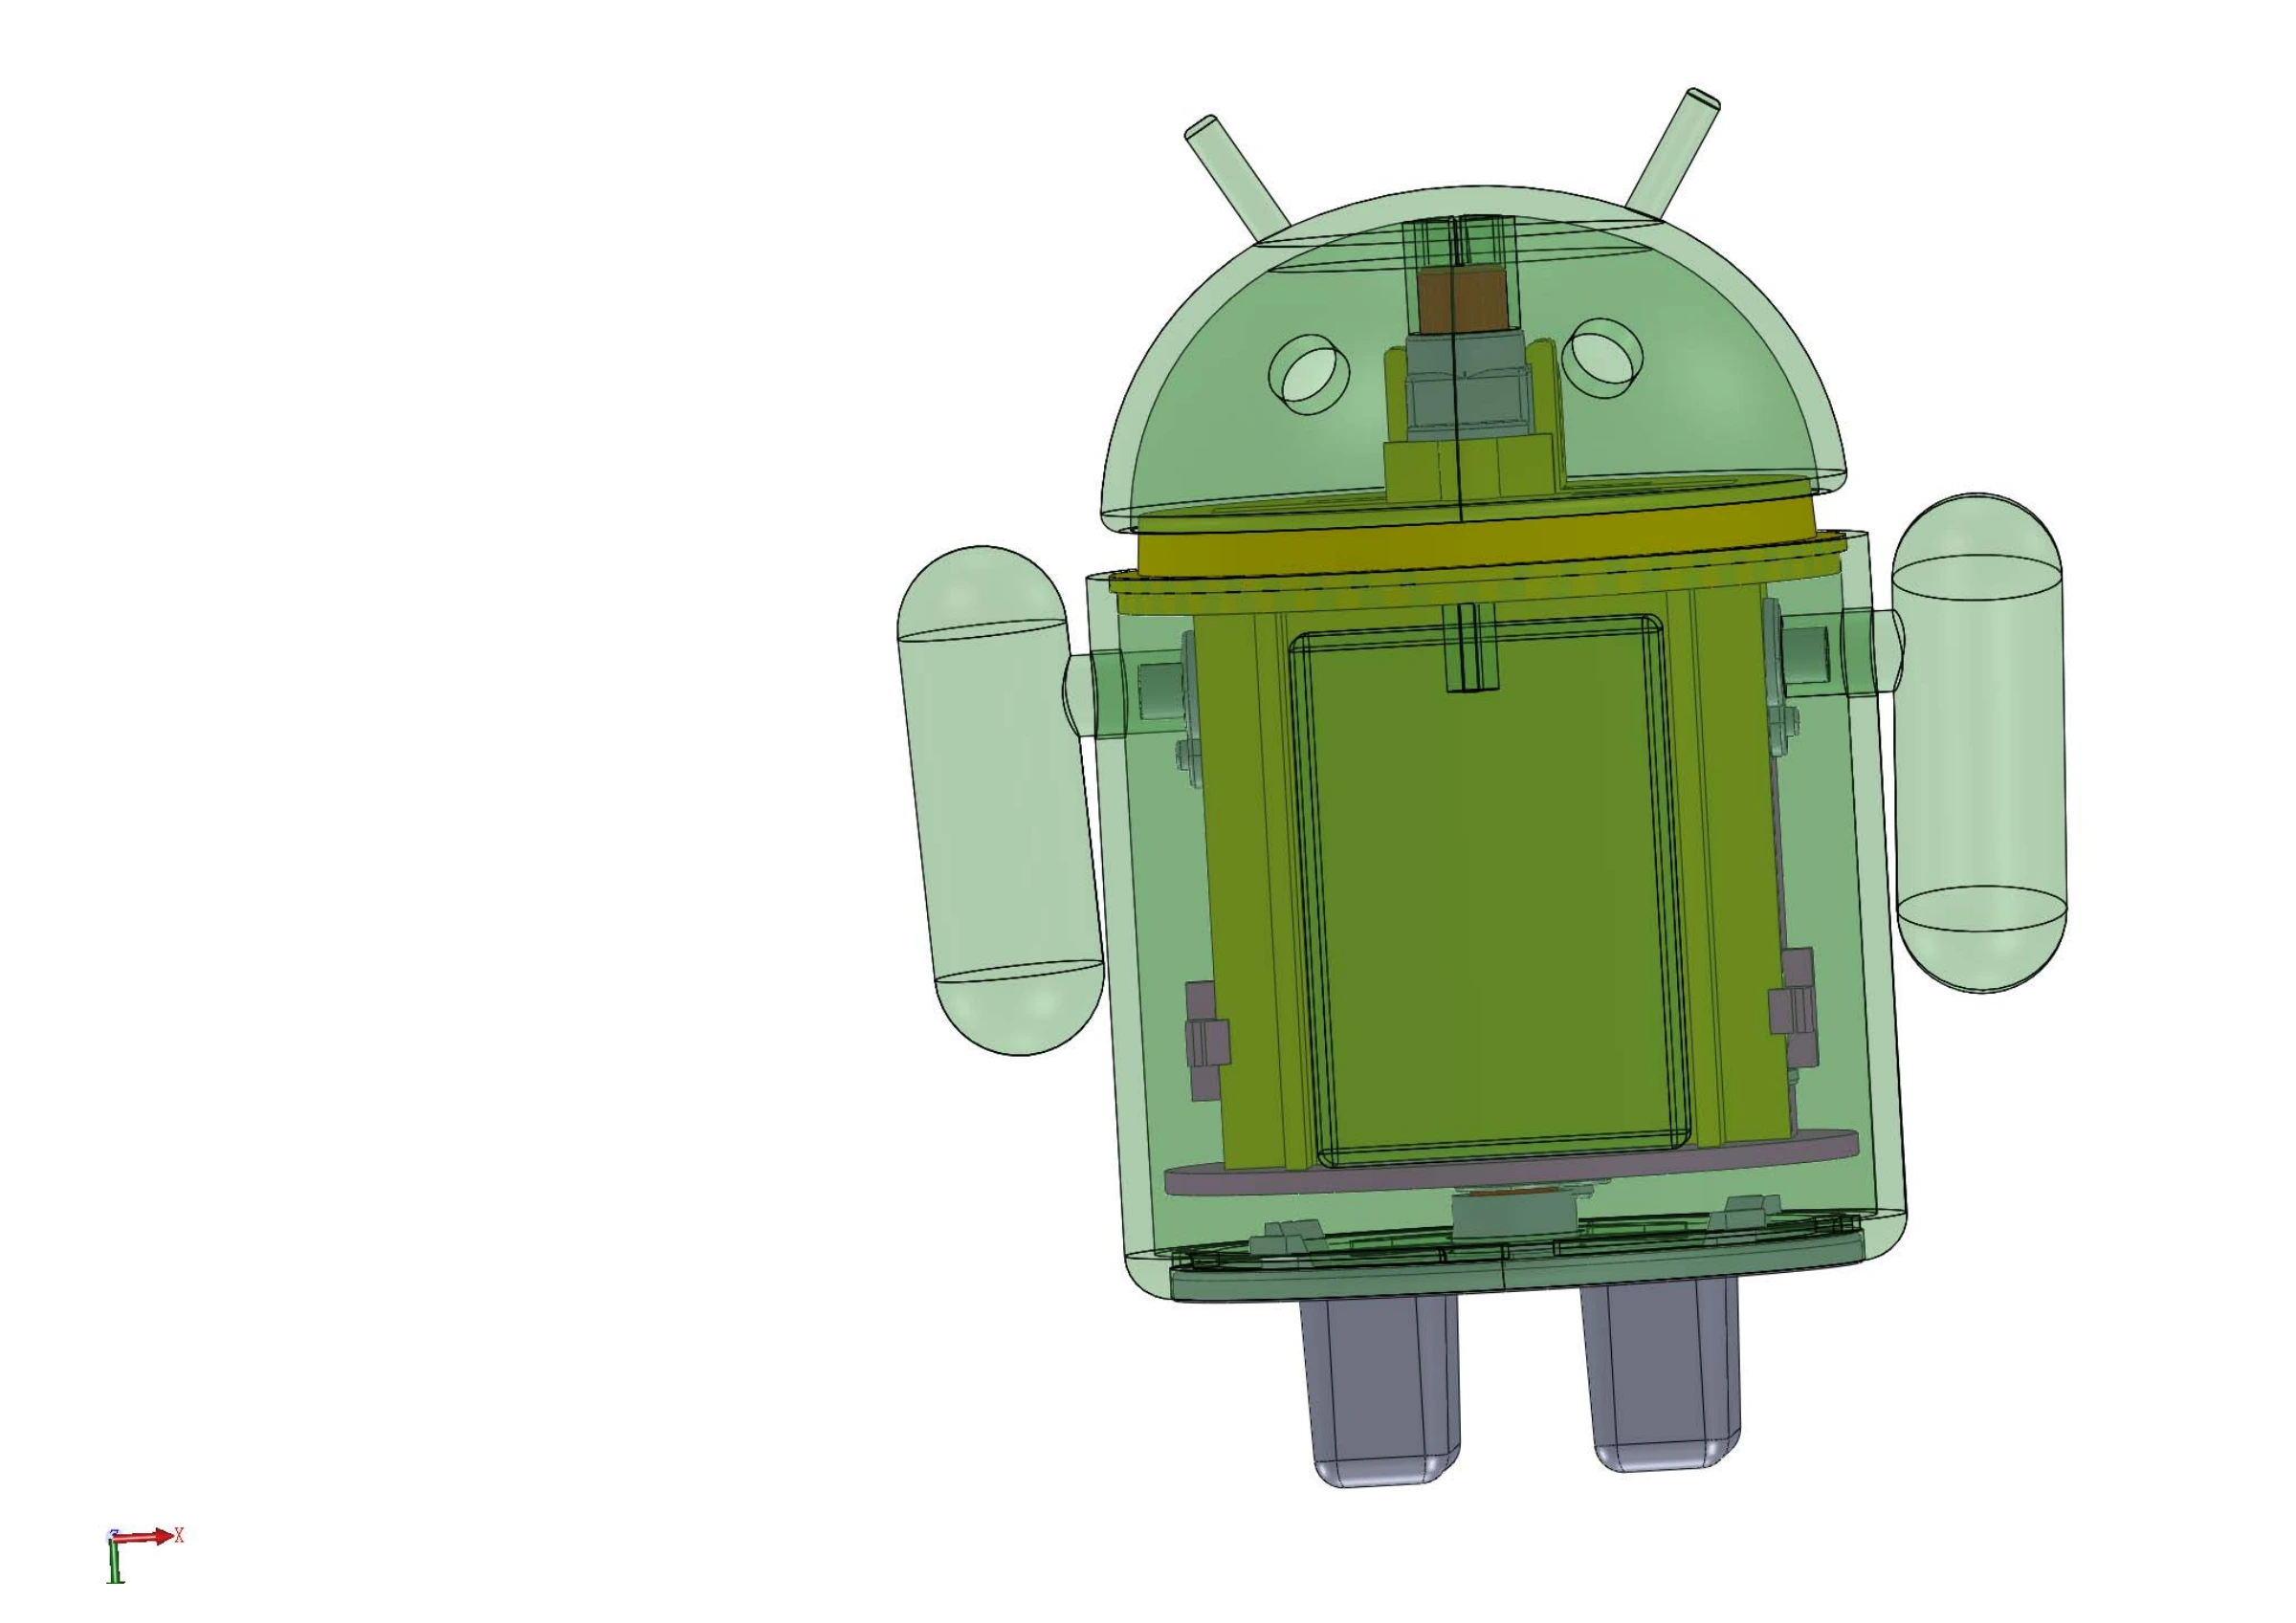
    A transparent-shell CAD view shows the internal assembly in place beneath the Android character’s familiar exterior.
    The assembled robotOriginal PDF
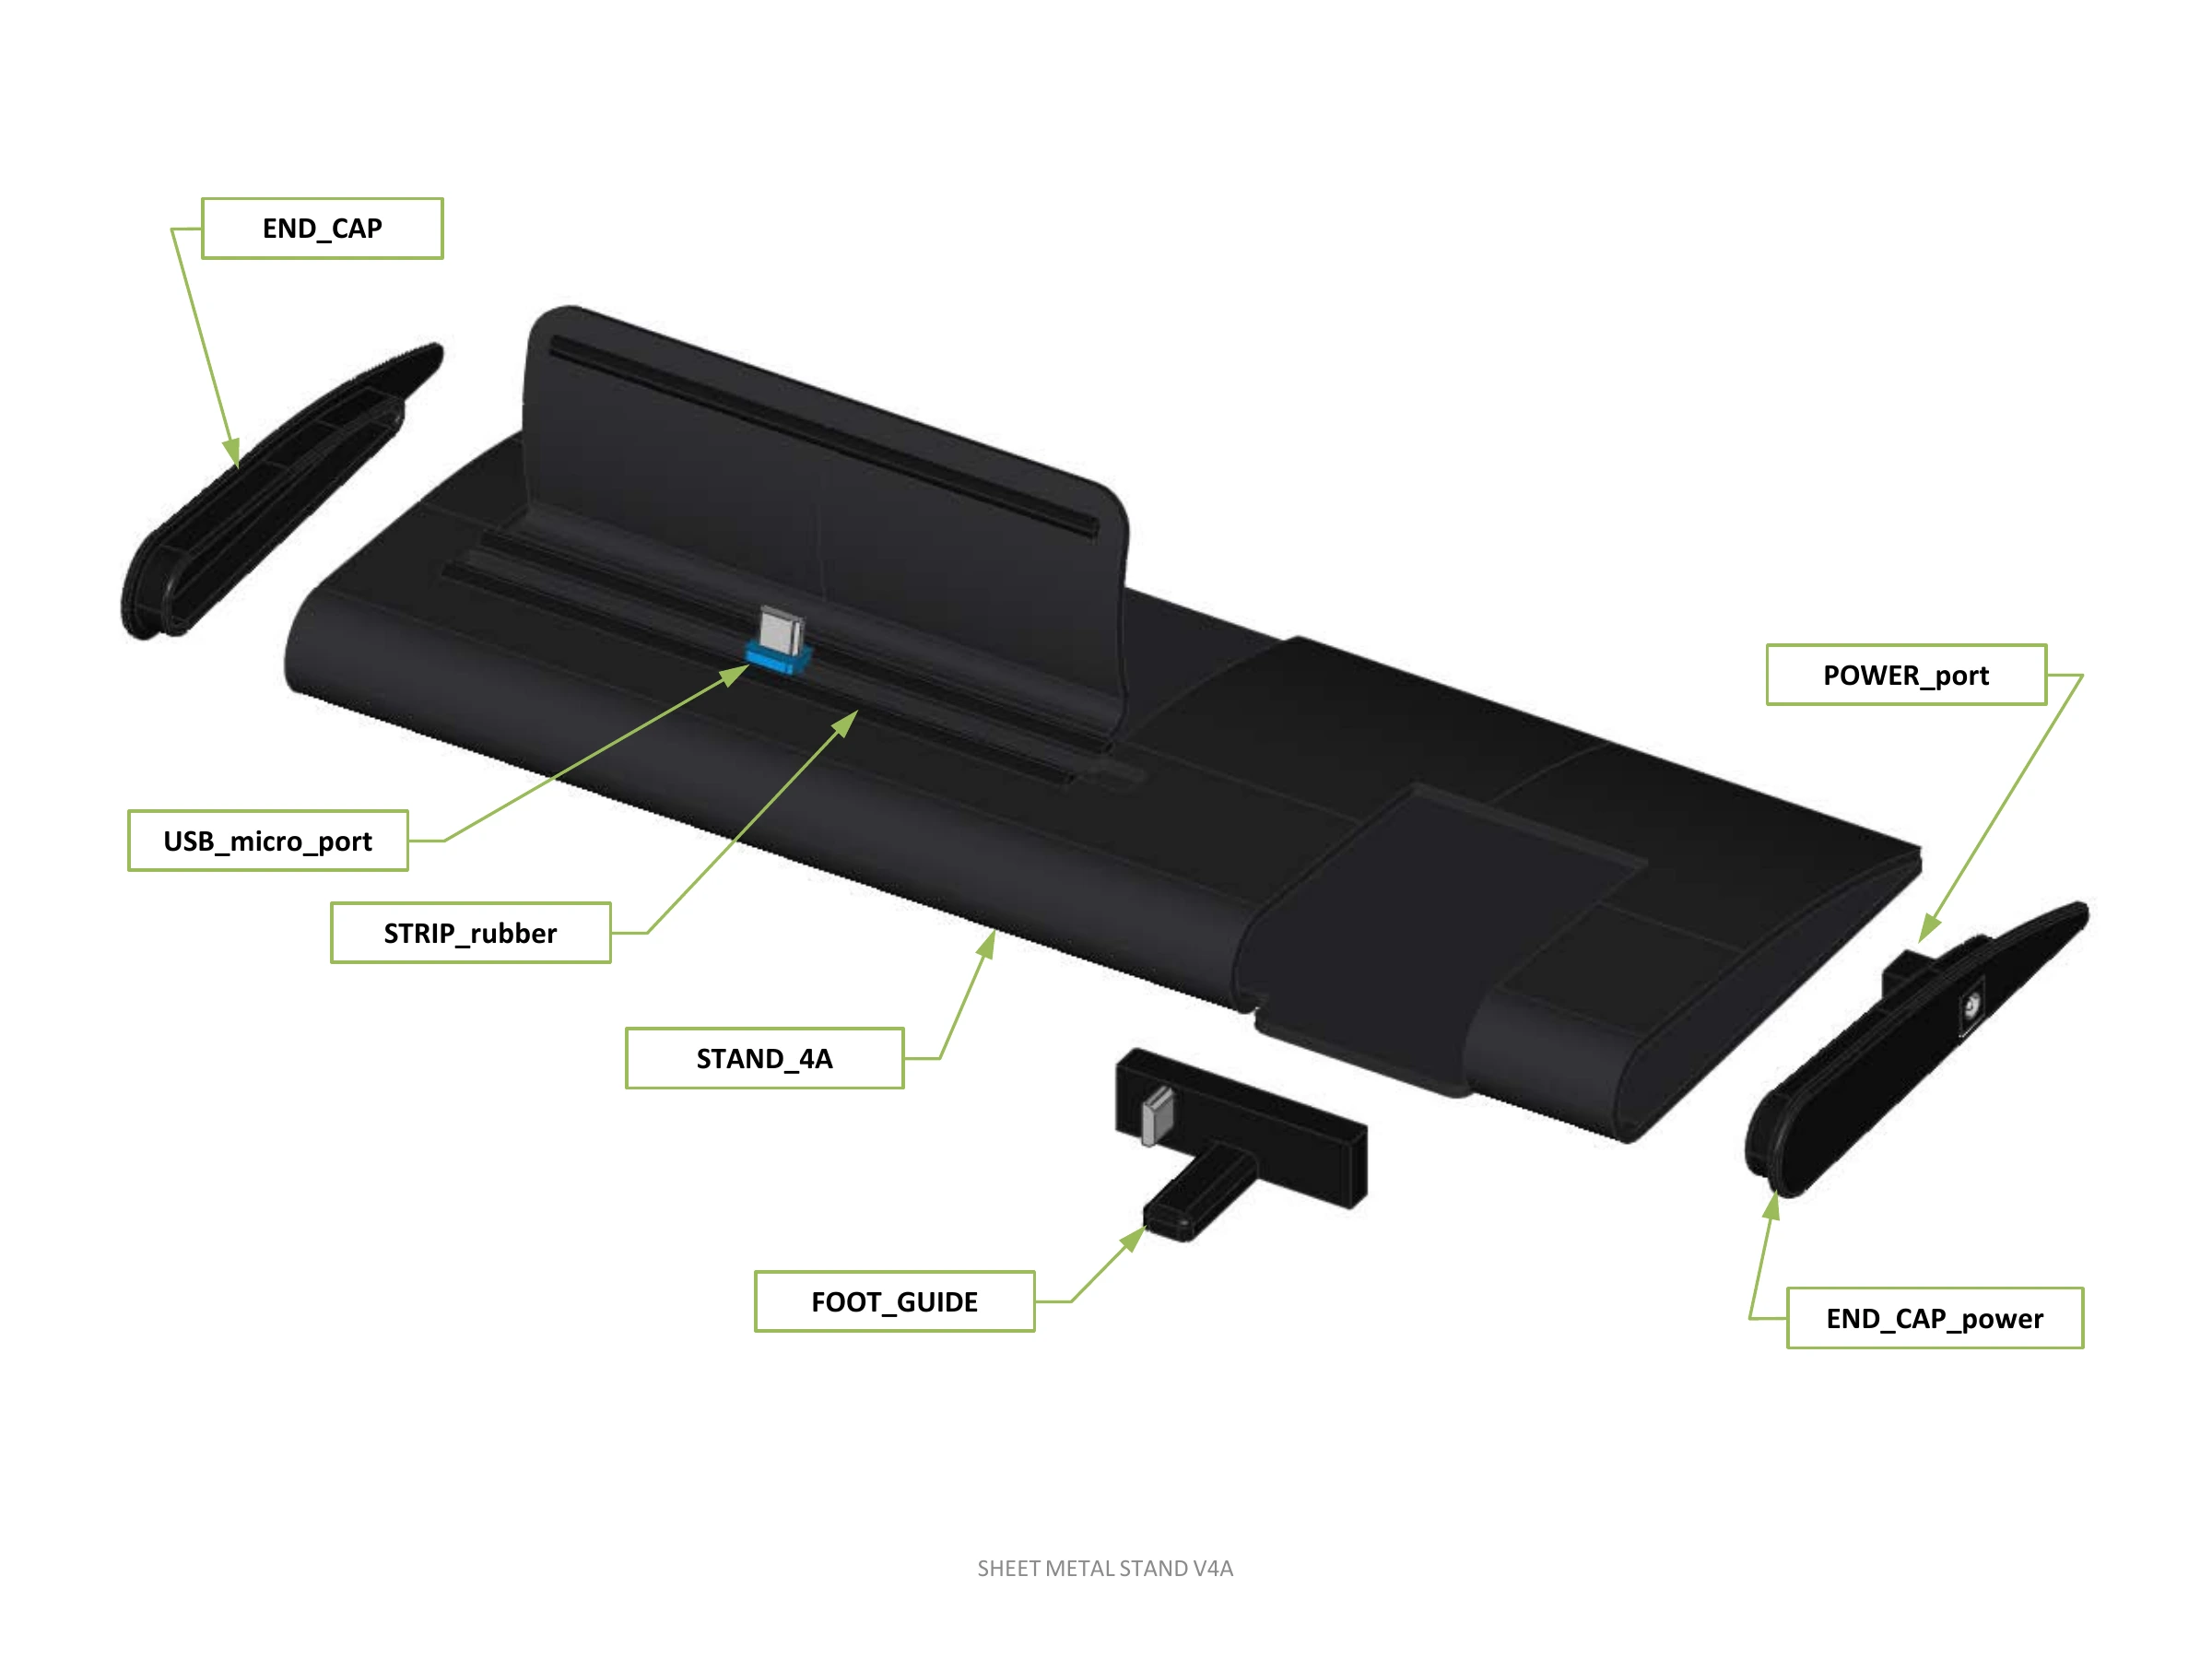
    The stand’s exploded assembly identifies the micro-USB connector, power port, end caps, rubber strip and foot guide. Sheet Metal Stand V4A, page 3.
    Connecting the physical piecesOriginal PDF
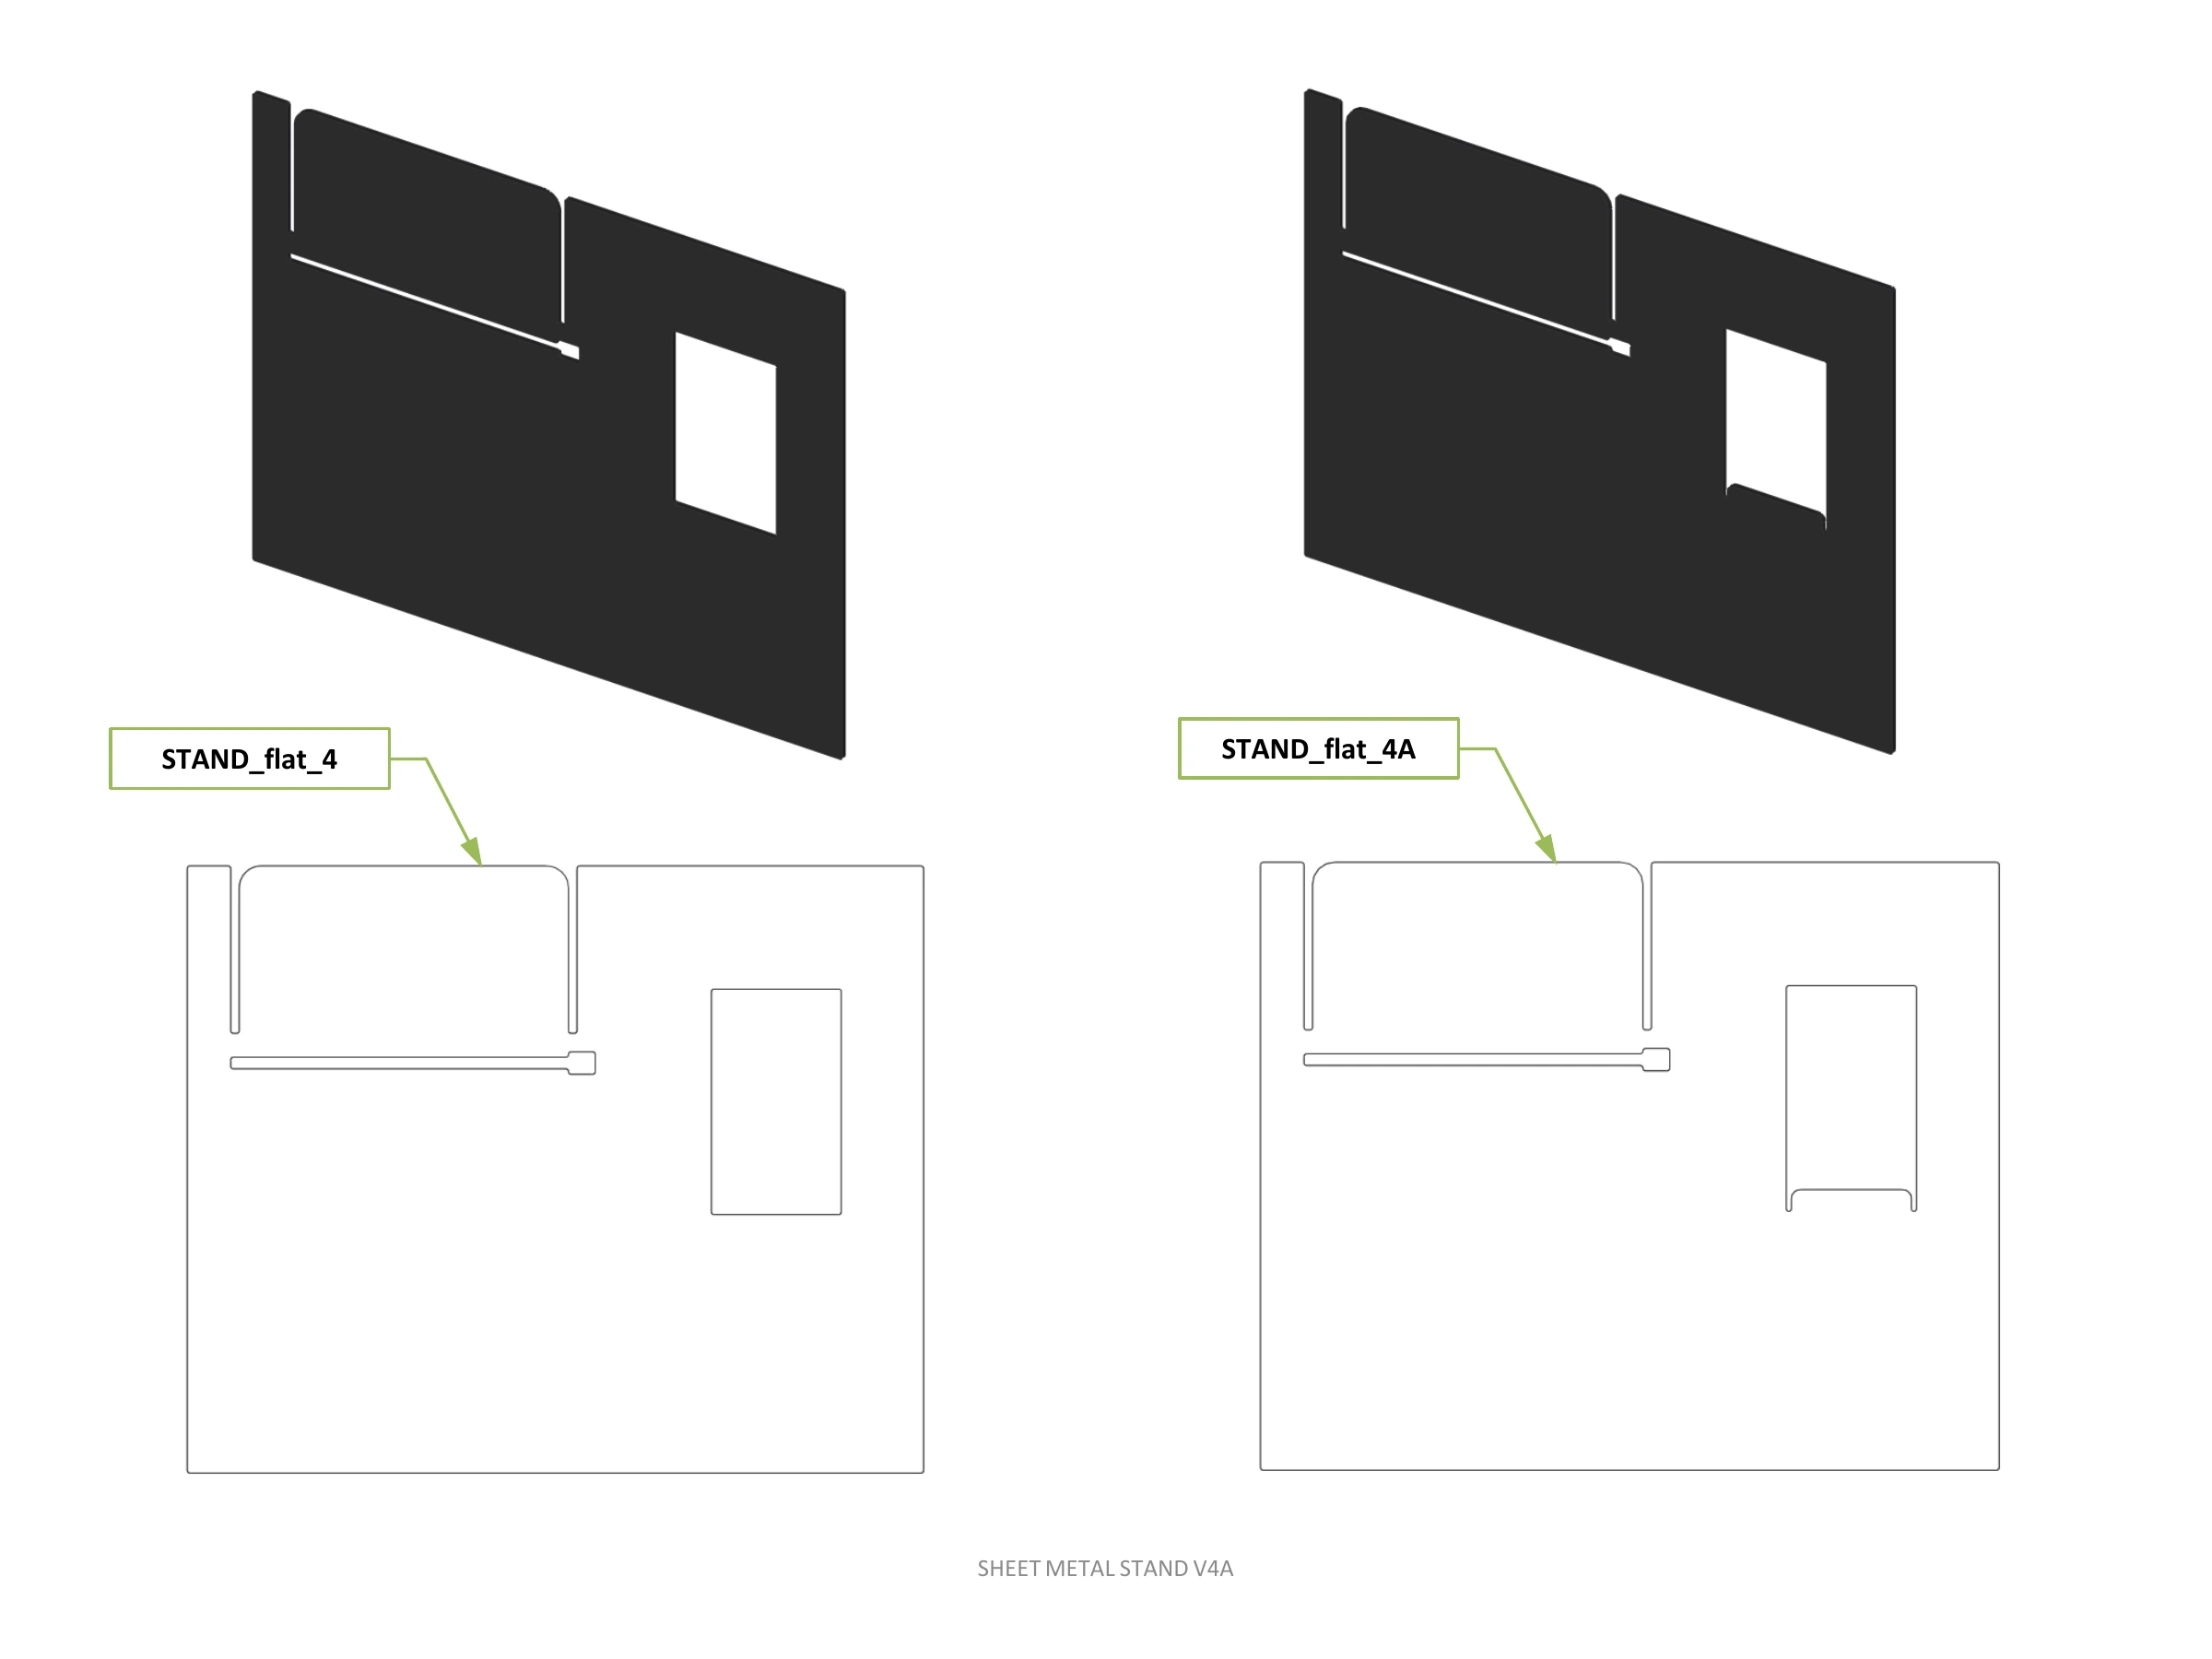
    Two stand variants shown as shaded CAD views and flat patterns. Sheet Metal Stand V4A, page 4.
    From a flat sheet to a standOriginal PDF
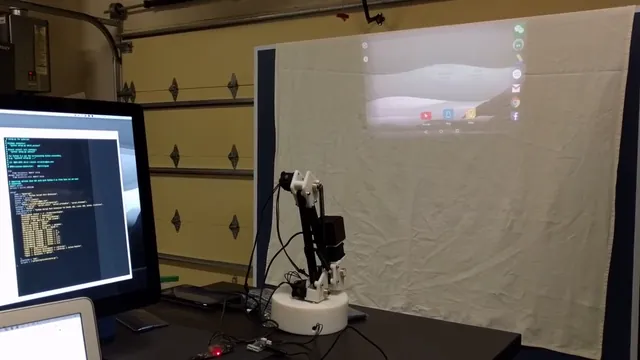
    An articulated device mount moving in front of a projection screen in a workshop.
    Giving a device movement
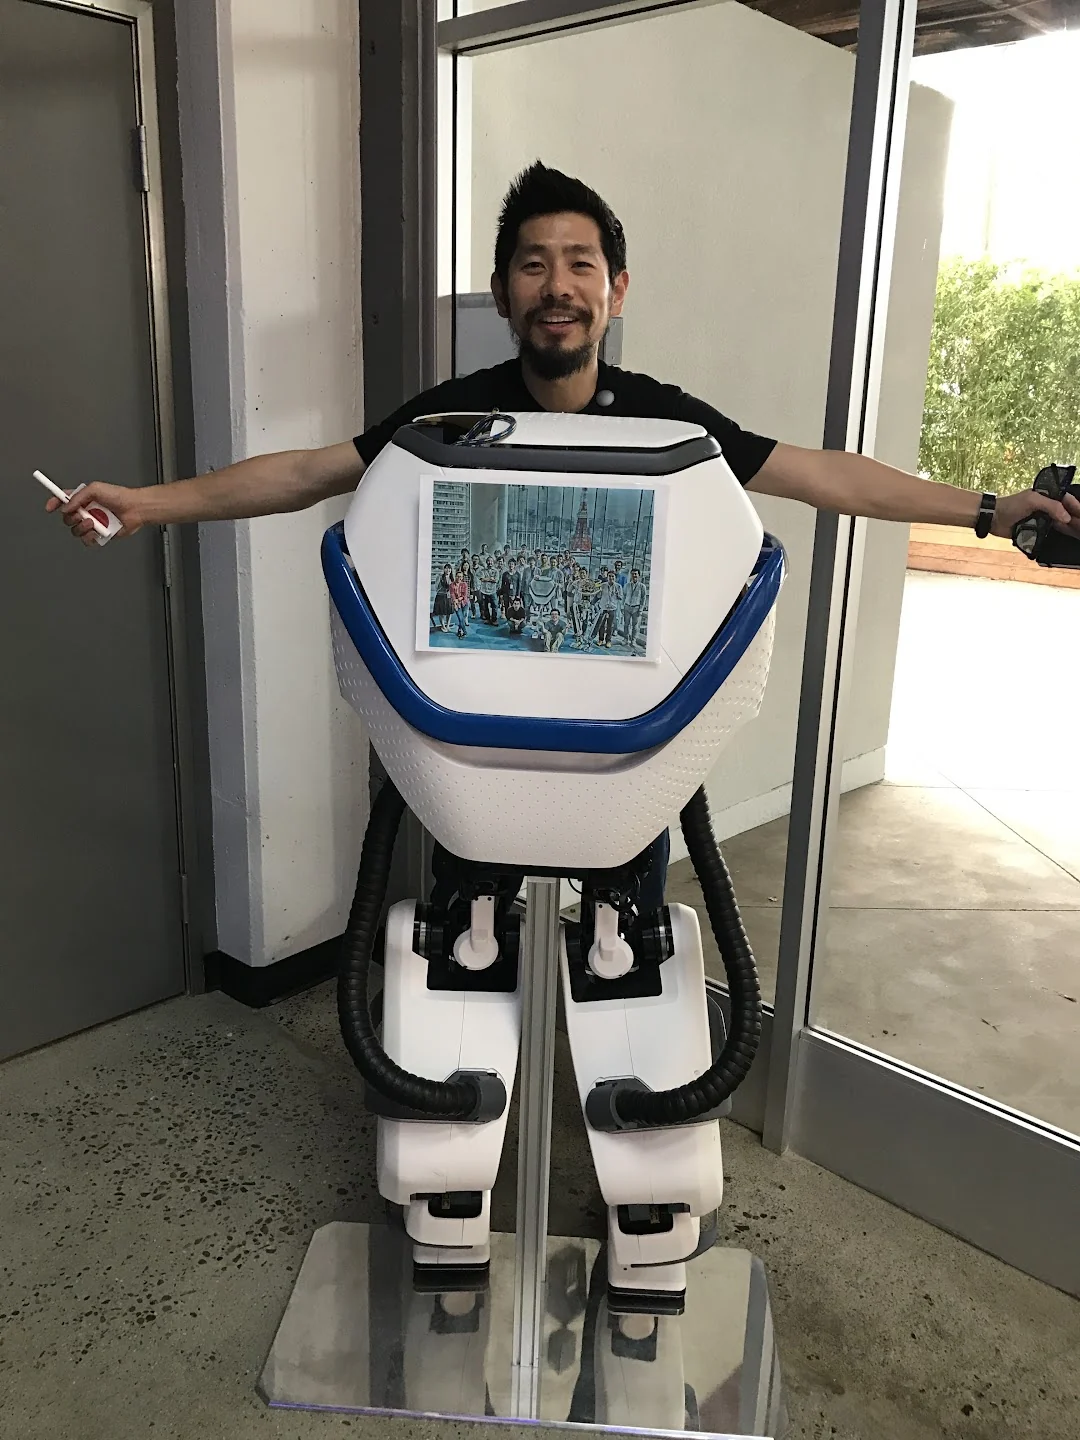
    A personal photograph with a full-size robot. An encounter along the way.
    Never quite outgrowing it
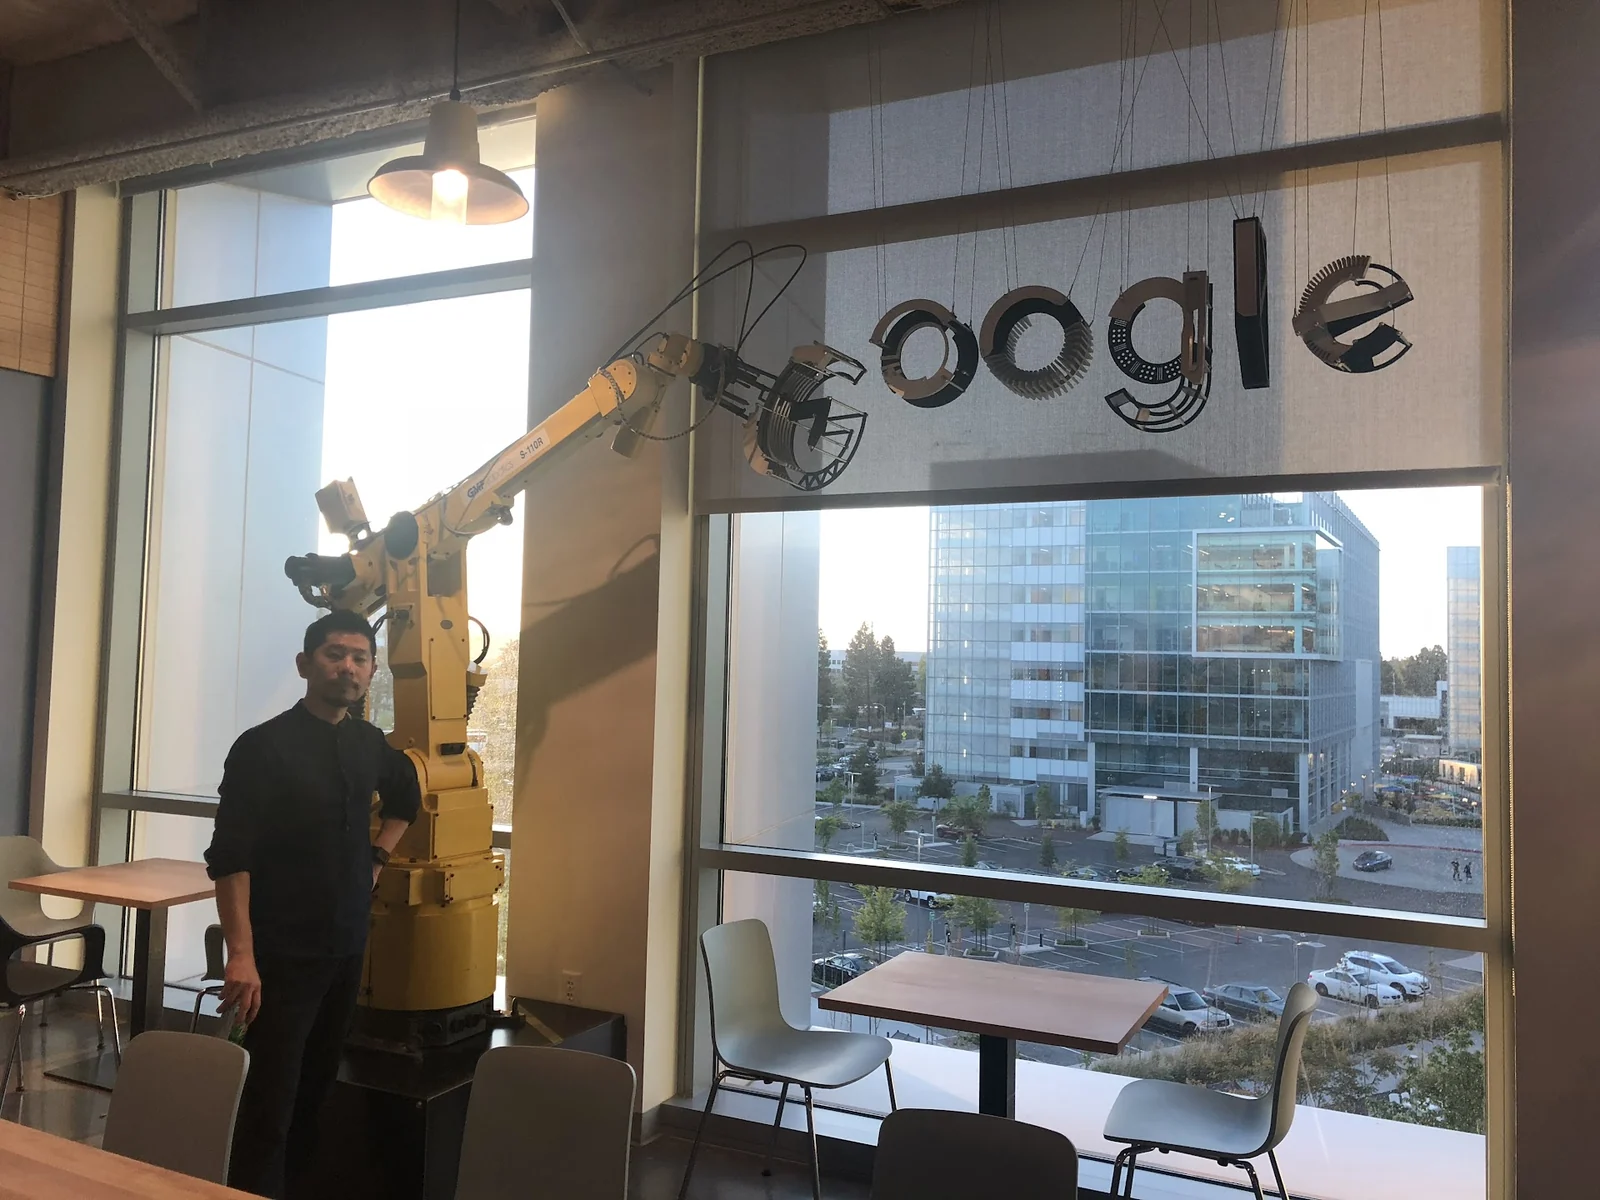
    A personal photograph beside an industrial robot at Google.
    Robots around the corner
    A tabletop prototype and projection setup during testing.
    Testing on the table
    An exposed humanoid robot on a support rig at a robotics event. From the personal archive.
    Meeting other machines

    Drawings archived in 2012. Android robot adapted from work created and shared by Google, used under CC BY 3.0.

  2. Let people make the character their own.

    I led the marketing team behind Androidify and continued the Dead Zebra collaboration, developing creative and working with partners on merchandising.

  3. Physical AI

    Open full view
    From imagining machines to working beside them.
    A robot people could make their own.

Founder, Builder, Marketer.

  • 10 years at early Google.
  • 0 to 1B Android devices.
  • $20M R&D lab I co-founded at X.
  • 30K laser headphones I invented. Acquired.
  • 1.5M users on a social wallet.

Dad, husband, runner.

  • 2,000 miles a year.
  • 27 marathons.
  • 2 people I run home to.
  • Still chasing Boston.
2026